<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://saran.sankaran.dev/feed.xml" rel="self" type="application/atom+xml" /><link href="https://saran.sankaran.dev/" rel="alternate" type="text/html" /><updated>2026-08-30T10:34:06+05:30</updated><id>https://saran.sankaran.dev/feed.xml</id><title type="html">Saran Sankaran</title><subtitle>Saran&apos;s personal blog</subtitle><author><name>Saran</name></author><entry><title type="html">How the R8 Configuration Analyser Cut Our App Size by 20% and Boosted Startup Speed</title><link href="https://saran.sankaran.dev/android/How-the-R8-Configuration-Analyser-Cut-Our-App-Size-by-20-and-Boosted-Startup-Speed/" rel="alternate" type="text/html" title="How the R8 Configuration Analyser Cut Our App Size by 20% and Boosted Startup Speed" /><published>2026-08-29T05:30:00+05:30</published><updated>2026-08-29T05:30:00+05:30</updated><id>https://saran.sankaran.dev/android/How-the-R8-Configuration-Analyser-Cut-Our-App-Size-by-20-and-Boosted-Startup-Speed</id><content type="html" xml:base="https://saran.sankaran.dev/android/How-the-R8-Configuration-Analyser-Cut-Our-App-Size-by-20-and-Boosted-Startup-Speed/"><![CDATA[<p>A few days ago, I came across a blog post on the Android Developers Blog about <a href="https://android-developers.googleblog.com/2026/08/tinder-app-cold-start-r8-configuration-analyzer.html">how Tinder optimised their app using the R8 Configuration Analyzer</a>. In my 8+ years of Android development experience, I had never heard of this tool before. This got me curious, so I started exploring what it does and how it works. The R8 Configuration Analyzer is a new tool available starting with Android Gradle Plugin (AGP) 9.3. It is essentially a Gradle task that analyses R8 configuration files (typically <code class="language-plaintext highlighter-rouge">proguard-rules.pro</code> and consumer rules) and provides insights into how each rule affects whether classes, fields, and methods are kept or removed during R8 optimisation. The Tinder case study builds on a previous post from a few months ago explaining <a href="https://android-developers.googleblog.com/2026/07/how-r8-made-kotlin-coroutines-2x-faster.html">how R8 made Kotlin Coroutines on Android 2x faster</a>.</p>

<h2 id="r8-configuration-analyzer">R8 Configuration Analyzer</h2>

<p>The R8 Configuration Analyzer is available for projects using AGP 9.3 and above. It runs as a Gradle task formatted as <code class="language-plaintext highlighter-rouge">:app:analyze&lt;Variant&gt;R8Config</code> (for example, <code class="language-plaintext highlighter-rouge">:app:analyzeReleaseR8Config</code> or <code class="language-plaintext highlighter-rouge">:app:analyzeDebugR8Config</code>). If your project uses product flavours, you combine the build type and flavour name accordingly (such as <code class="language-plaintext highlighter-rouge">:app:analyzeGithubReleaseR8Config</code>). The interesting part is that running this task does not build the entire app. It only compiles classes and resources, stopping short of running full R8 optimisation and assembling the final AAB or APK which is time consuming.</p>

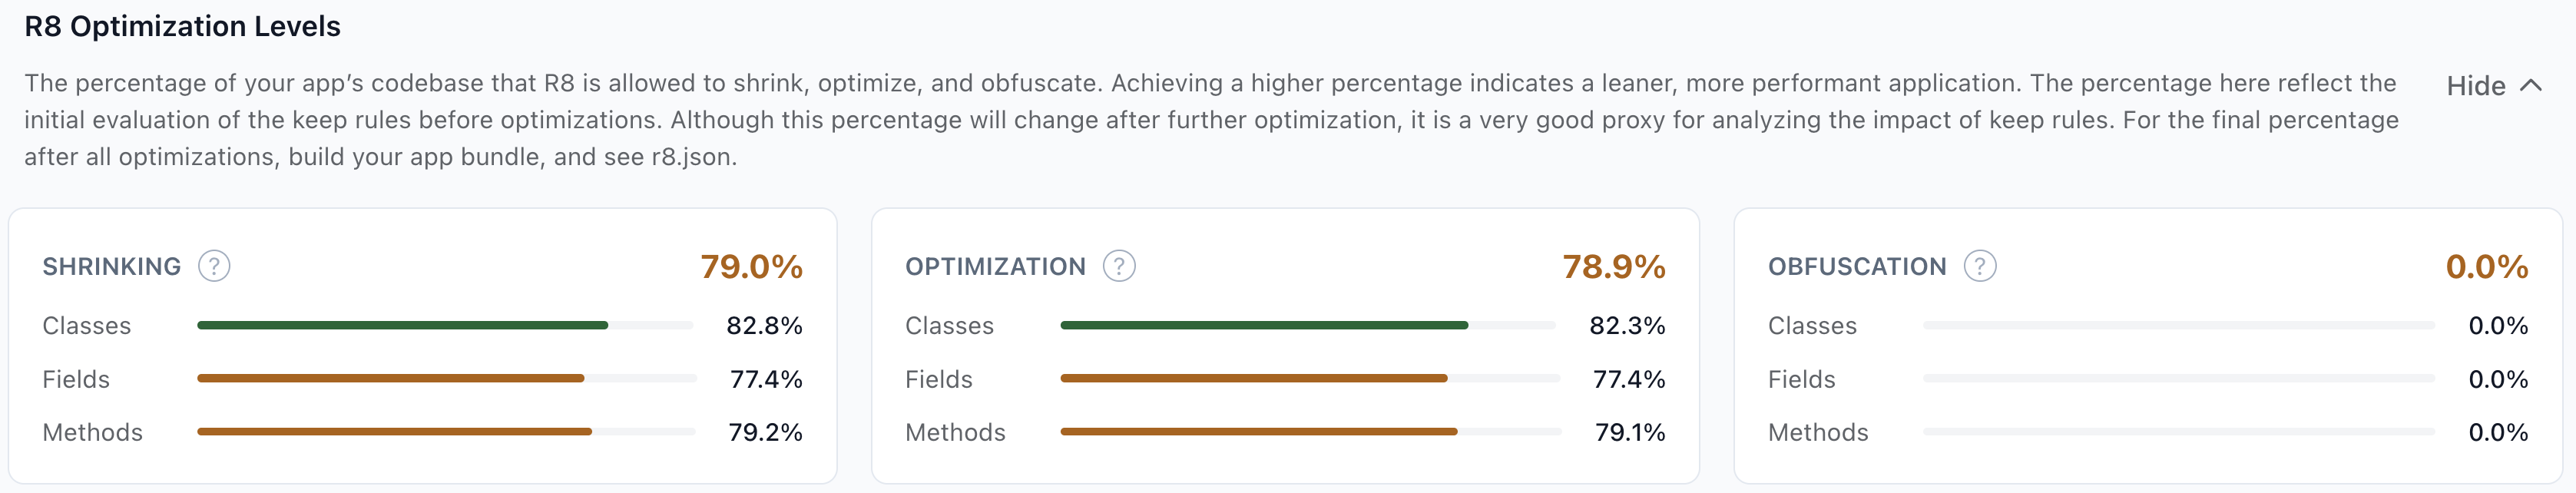
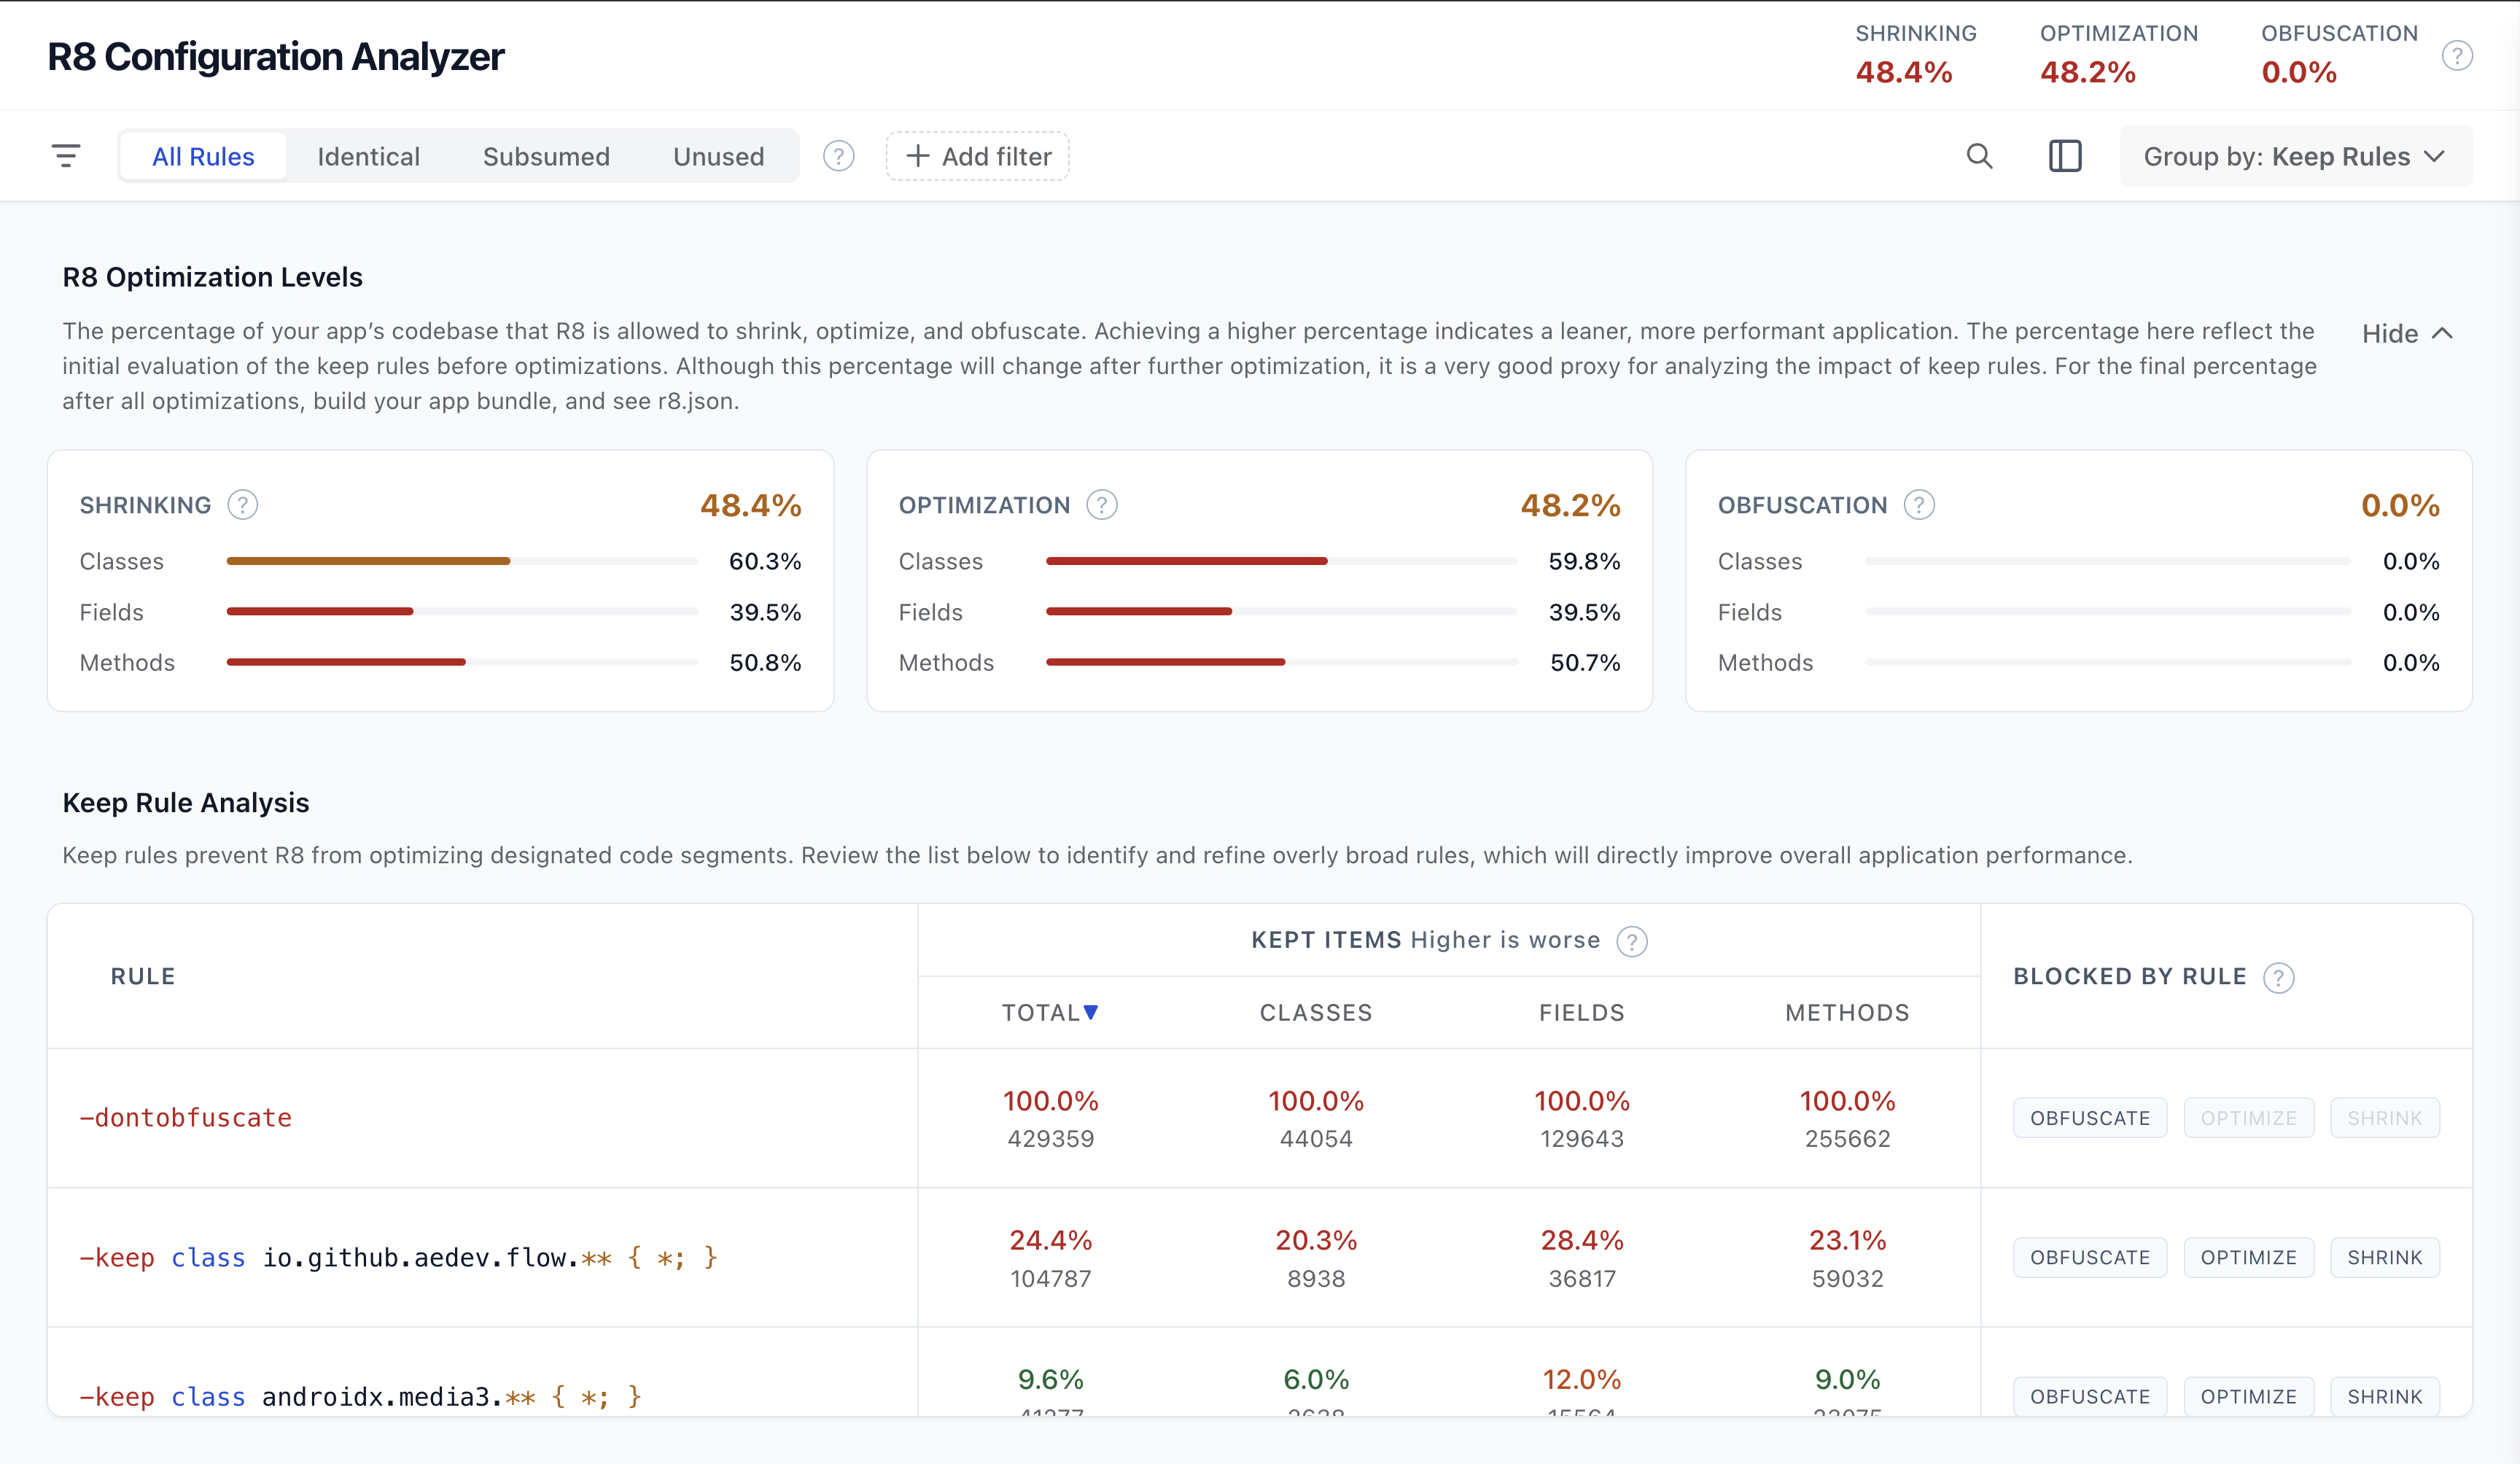
<p>When the Gradle task completes, it generates an HTML report showing how R8 keep rules affect the compiled classes. It displays percentage scores for how much of the app’s codebase R8 is allowed to shrink, optimise, and obfuscate. The higher the percentage, the better for the app’s size and runtime performance.</p>

<figure class="align-center">
  <img src="/assets/images/R8_example_report.png" alt="R8 Configuration Analyzer HTML report" />
  <figcaption>R8 Configuration Analyzer HTML report showing overall optimisation scores and keep rule analysis.</figcaption>
</figure>

<h2 id="usage-in-actual-app">Usage in actual app</h2>

<p>To test this out in practice, I picked an open-source app that I actively contribute to: <a href="https://github.com/A-EDev/Flow">Flow</a>, a YouTube client reimagined for Android. Before making any optimisations, I ran <code class="language-plaintext highlighter-rouge">./gradlew :app:analyzeGithubReleaseR8Config</code> to establish a baseline.</p>

<p>I studied the generated report and used the <code class="language-plaintext highlighter-rouge">android-cli</code> tool’s <code class="language-plaintext highlighter-rouge">r8-analyzer</code> agent skill to investigate potential optimisations. After the agent generated its analysis and recommendations, I asked it to optimise the configuration accordingly. Since Flow is an open-source project, code obfuscation isn’t necessary, so we use the <code class="language-plaintext highlighter-rouge">-dontobfuscate</code> flag. After going through a few rounds of iterative refinement with the AI agent to tighten overly broad keep rules, I verified and committed the code. I also used this opportunity to benchmark app startup times and submitted everything in a combined <a href="https://github.com/A-EDev/Flow/pull/933">PR</a>.</p>

<p class="notice--success"><strong>Pro tip:</strong> Always copy the generated HTML report outside the <code class="language-plaintext highlighter-rouge">build/</code> directory so you don’t accidentally overwrite it when modifying keep rules and regenerating the report. Without the initial baseline report, it becomes difficult to compare whether your rule modifications changed anything.</p>

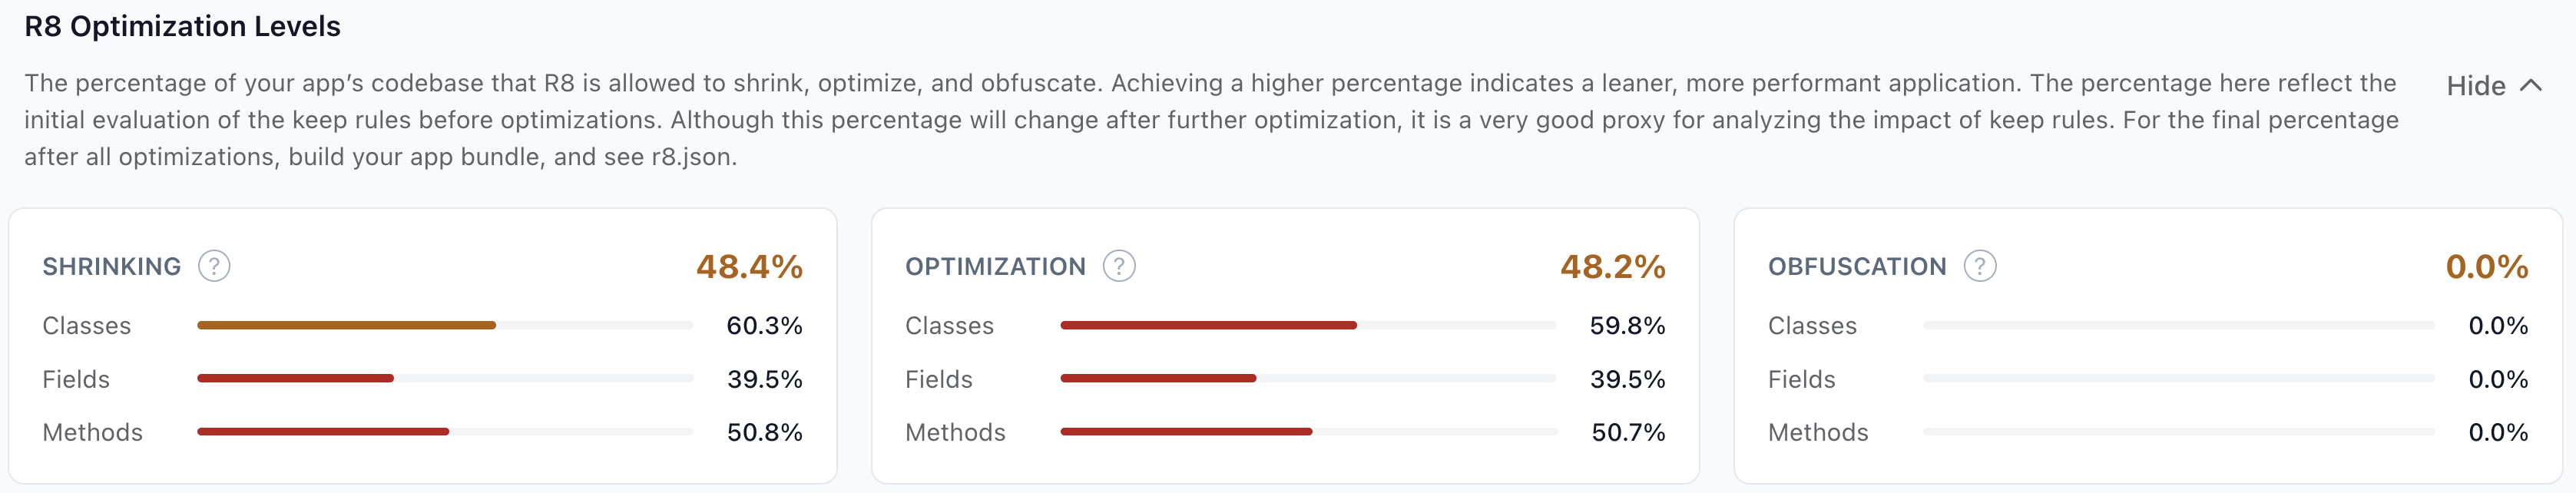
<p>After this optimisation, I was able to <strong>shave off ~20% of the APK size</strong> and achieve an <strong>~11% faster warm startup</strong>.</p>

<figure class="align-center">
  <img src="/assets/images/before_r8_optimisation.png" alt="Optimisation scores before cleanup" />
  <figcaption>Optimisation scores before R8 configuration cleanup (48.4% shrinking, 48.2% optimisation).</figcaption>
</figure>

<figure class="align-center">
  <img src="/assets/images/after_r8_optimisation.png" alt="Optimisation scores after cleanup" />
  <figcaption>Optimisation scores after R8 configuration cleanup (79.0% shrinking, 78.9% optimisation).</figcaption>
</figure>

<h2 id="pros">Pros</h2>

<ul>
  <li>Generates a clear, shareable report showing the exact optimisation gains achieved.</li>
  <li>Provides much-needed visibility into what each ProGuard/R8 rule is actually doing.</li>
  <li>Fast execution because it avoids running full R8 or generating final package artifacts.</li>
  <li>Comes with an agent skill (<code class="language-plaintext highlighter-rouge">r8-analyzer</code>) that speeds up investigation and fixes.</li>
</ul>

<h2 id="cons">Cons</h2>

<ul>
  <li>The report does not estimate the exact byte-level APK size savings gained from each rule change.</li>
  <li>You cannot simulate rule adjustments directly in the report interface without updating the rules file and re-running the Gradle task.</li>
  <li>The “Group by Keep Rule File” view is somewhat cumbersome, as you have to inspect each rule file individually to review its available optimisations.</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>This tool is a big step in the right direction. Previously, Android developers lacked clear visibility into how individual keep rules impacted overall app optimisation. With the R8 Configuration Analyzer, we can easily see how each rule affects the codebase and fine-tune our configurations for leaner, faster apps.</p>]]></content><author><name>Saran</name></author><category term="Android" /><category term="Android" /><category term="R8" /><category term="ProGuard" /><category term="Performance" /><summary type="html"><![CDATA[A few days ago, I came across a blog post on the Android Developers Blog about how Tinder optimised their app using the R8 Configuration Analyzer. In my 8+ years of Android development experience, I had never heard of this tool before. This got me curious, so I started exploring what it does and how it works. The R8 Configuration Analyzer is a new tool available starting with Android Gradle Plugin (AGP) 9.3. It is essentially a Gradle task that analyses R8 configuration files (typically proguard-rules.pro and consumer rules) and provides insights into how each rule affects whether classes, fields, and methods are kept or removed during R8 optimisation. The Tinder case study builds on a previous post from a few months ago explaining how R8 made Kotlin Coroutines on Android 2x faster. R8 Configuration Analyzer The R8 Configuration Analyzer is available for projects using AGP 9.3 and above. It runs as a Gradle task formatted as :app:analyze&lt;Variant&gt;R8Config (for example, :app:analyzeReleaseR8Config or :app:analyzeDebugR8Config). If your project uses product flavours, you combine the build type and flavour name accordingly (such as :app:analyzeGithubReleaseR8Config). The interesting part is that running this task does not build the entire app. It only compiles classes and resources, stopping short of running full R8 optimisation and assembling the final AAB or APK which is time consuming. When the Gradle task completes, it generates an HTML report showing how R8 keep rules affect the compiled classes. It displays percentage scores for how much of the app’s codebase R8 is allowed to shrink, optimise, and obfuscate. The higher the percentage, the better for the app’s size and runtime performance. R8 Configuration Analyzer HTML report showing overall optimisation scores and keep rule analysis. Usage in actual app To test this out in practice, I picked an open-source app that I actively contribute to: Flow, a YouTube client reimagined for Android. Before making any optimisations, I ran ./gradlew :app:analyzeGithubReleaseR8Config to establish a baseline. I studied the generated report and used the android-cli tool’s r8-analyzer agent skill to investigate potential optimisations. After the agent generated its analysis and recommendations, I asked it to optimise the configuration accordingly. Since Flow is an open-source project, code obfuscation isn’t necessary, so we use the -dontobfuscate flag. After going through a few rounds of iterative refinement with the AI agent to tighten overly broad keep rules, I verified and committed the code. I also used this opportunity to benchmark app startup times and submitted everything in a combined PR. Pro tip: Always copy the generated HTML report outside the build/ directory so you don’t accidentally overwrite it when modifying keep rules and regenerating the report. Without the initial baseline report, it becomes difficult to compare whether your rule modifications changed anything. After this optimisation, I was able to shave off ~20% of the APK size and achieve an ~11% faster warm startup. Optimisation scores before R8 configuration cleanup (48.4% shrinking, 48.2% optimisation). Optimisation scores after R8 configuration cleanup (79.0% shrinking, 78.9% optimisation). Pros Generates a clear, shareable report showing the exact optimisation gains achieved. Provides much-needed visibility into what each ProGuard/R8 rule is actually doing. Fast execution because it avoids running full R8 or generating final package artifacts. Comes with an agent skill (r8-analyzer) that speeds up investigation and fixes. Cons The report does not estimate the exact byte-level APK size savings gained from each rule change. You cannot simulate rule adjustments directly in the report interface without updating the rules file and re-running the Gradle task. The “Group by Keep Rule File” view is somewhat cumbersome, as you have to inspect each rule file individually to review its available optimisations. Conclusion This tool is a big step in the right direction. Previously, Android developers lacked clear visibility into how individual keep rules impacted overall app optimisation. With the R8 Configuration Analyzer, we can easily see how each rule affects the codebase and fine-tune our configurations for leaner, faster apps.]]></summary></entry><entry><title type="html">Protobuf vs JSON: The Compression Test That Changed My Mind</title><link href="https://saran.sankaran.dev/grpc/Protobuf-vs-JSON-The-Compression-Test-That-Changed-My-Mind/" rel="alternate" type="text/html" title="Protobuf vs JSON: The Compression Test That Changed My Mind" /><published>2024-12-26T05:30:00+05:30</published><updated>2024-12-26T05:30:00+05:30</updated><id>https://saran.sankaran.dev/grpc/Protobuf-vs-JSON-The-Compression-Test-That-Changed-My-Mind</id><content type="html" xml:base="https://saran.sankaran.dev/grpc/Protobuf-vs-JSON-The-Compression-Test-That-Changed-My-Mind/"><![CDATA[<p>A few days back I was debating with a friend about REST vs gRPC in the context of client-server communication over the Internet. Where I was in favour of gRPC. During our debate, I jumped quickly to say protobuf are more optimised than JSON because they omit unwanted data. To which my friend replied that we don’t transfer plain JSON over the network anymore we always gzip them before sending them. He explained further, that all the optimisation that gRPC does is lost when we gzip the data. I couldn’t continue to argue my point because I didn’t have enough data to prove my point. Thus I decided to run an experiment to compare the size after gziping JSON vs Protobuf.</p>
<p>Since I was in the process of learning go language from scratch, I decided to use it for this experiment.</p>

<h3 id="code">Code</h3>
<div class="language-go highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">var</span> <span class="n">UserCounts</span> <span class="o">=</span> <span class="p">[</span><span class="o">...</span><span class="p">]</span><span class="kt">int</span><span class="p">{</span><span class="m">1</span><span class="p">,</span> <span class="m">10</span><span class="p">,</span> <span class="m">100</span><span class="p">,</span> <span class="m">1000</span><span class="p">,</span> <span class="m">10000</span><span class="p">,</span> <span class="m">100000</span><span class="p">,</span> <span class="m">1000000</span><span class="p">}</span>

<span class="k">func</span> <span class="n">main</span><span class="p">()</span> <span class="p">{</span>
    <span class="n">names</span> <span class="o">:=</span> <span class="n">readUsername</span><span class="p">(</span><span class="n">usernamesFile</span><span class="p">)</span>

    <span class="n">usersList</span> <span class="o">:=</span> <span class="n">UsersProto</span><span class="p">{</span>
        <span class="n">Users</span><span class="o">:</span> <span class="p">[]</span><span class="o">*</span><span class="n">UserProto</span><span class="p">{},</span>
    <span class="p">}</span>

    <span class="n">writer</span> <span class="o">:=</span> <span class="n">tabwriter</span><span class="o">.</span><span class="n">NewWriter</span><span class="p">(</span><span class="n">os</span><span class="o">.</span><span class="n">Stdout</span><span class="p">,</span> <span class="m">0</span><span class="p">,</span> <span class="m">0</span><span class="p">,</span> <span class="m">1</span><span class="p">,</span> <span class="sc">' '</span><span class="p">,</span> <span class="n">tabwriter</span><span class="o">.</span><span class="n">Debug</span><span class="p">)</span>
    <span class="n">fmt</span><span class="o">.</span><span class="n">Fprintln</span><span class="p">(</span><span class="n">writer</span><span class="p">,</span> <span class="s">"Users</span><span class="se">\t</span><span class="s">JSON Size</span><span class="se">\t</span><span class="s">Gzipped JSON Size</span><span class="se">\t</span><span class="s">JSON Gzip size % </span><span class="se">\t</span><span class="s">Proto Size</span><span class="se">\t</span><span class="s">Gzipped Proto Size</span><span class="se">\t</span><span class="s">Proto Gzip size %</span><span class="se">\t</span><span class="s">Gzip Diff (JSON - Proto)"</span><span class="p">)</span>
    <span class="k">for</span> <span class="n">_</span><span class="p">,</span> <span class="n">num</span> <span class="o">:=</span> <span class="k">range</span> <span class="n">UserCounts</span> <span class="p">{</span>
        <span class="k">for</span> <span class="n">i</span> <span class="o">:=</span> <span class="m">0</span><span class="p">;</span> <span class="n">i</span> <span class="o">&lt;</span> <span class="n">num</span><span class="p">;</span> <span class="n">i</span><span class="o">++</span> <span class="p">{</span>

            <span class="n">name</span> <span class="o">:=</span> <span class="n">names</span><span class="p">[</span><span class="n">rand</span><span class="o">.</span><span class="n">IntN</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">names</span><span class="p">))]</span>
            <span class="n">user</span> <span class="o">:=</span> <span class="n">UserProto</span><span class="p">{</span>
                <span class="n">Name</span><span class="o">:</span>  <span class="n">name</span><span class="p">,</span>
                <span class="n">Age</span><span class="o">:</span>   <span class="n">rand</span><span class="o">.</span><span class="n">Int32N</span><span class="p">(</span><span class="m">91</span><span class="p">)</span> <span class="o">+</span> <span class="m">10</span><span class="p">,</span>
                <span class="n">Email</span><span class="o">:</span> <span class="n">fmt</span><span class="o">.</span><span class="n">Sprintf</span><span class="p">(</span><span class="s">"%s@gmail.com"</span><span class="p">,</span> <span class="n">name</span><span class="p">),</span>
            <span class="p">}</span>

            <span class="n">usersList</span><span class="o">.</span><span class="n">Users</span> <span class="o">=</span> <span class="nb">append</span><span class="p">(</span><span class="n">usersList</span><span class="o">.</span><span class="n">Users</span><span class="p">,</span> <span class="o">&amp;</span><span class="n">user</span><span class="p">)</span>
        <span class="p">}</span>

        <span class="n">jsonData</span><span class="p">,</span> <span class="n">_</span> <span class="o">:=</span> <span class="n">json</span><span class="o">.</span><span class="n">Marshal</span><span class="p">(</span><span class="n">usersList</span><span class="p">)</span>
        <span class="n">protData</span><span class="p">,</span> <span class="n">_</span> <span class="o">:=</span> <span class="n">proto</span><span class="o">.</span><span class="n">Marshal</span><span class="p">(</span><span class="o">&amp;</span><span class="n">usersList</span><span class="p">)</span>
        <span class="n">gzippedProtoSize</span> <span class="o">:=</span> <span class="n">gzipDataAndReturnSize</span><span class="p">(</span><span class="n">protData</span><span class="p">)</span>
        <span class="n">gzippedJsonSize</span> <span class="o">:=</span> <span class="n">gzipDataAndReturnSize</span><span class="p">(</span><span class="n">jsonData</span><span class="p">)</span>

        <span class="n">jsonReduction</span> <span class="o">:=</span> <span class="kt">float64</span><span class="p">(</span><span class="n">gzippedJsonSize</span><span class="p">)</span> <span class="o">/</span> <span class="kt">float64</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">jsonData</span><span class="p">))</span> <span class="o">*</span> <span class="m">100</span>
        <span class="n">protoReduction</span> <span class="o">:=</span> <span class="kt">float64</span><span class="p">(</span><span class="n">gzippedProtoSize</span><span class="p">)</span> <span class="o">/</span> <span class="kt">float64</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">protData</span><span class="p">))</span> <span class="o">*</span> <span class="m">100</span>
        <span class="n">diff</span> <span class="o">:=</span> <span class="n">gzippedJsonSize</span> <span class="o">-</span> <span class="n">gzippedProtoSize</span>

        <span class="n">fmt</span><span class="o">.</span><span class="n">Fprintf</span><span class="p">(</span><span class="n">writer</span><span class="p">,</span> <span class="s">"%d</span><span class="se">\t</span><span class="s">%s</span><span class="se">\t</span><span class="s">%s</span><span class="se">\t</span><span class="s">%.0f%%</span><span class="se">\t</span><span class="s">%s</span><span class="se">\t</span><span class="s">%s</span><span class="se">\t</span><span class="s">%.0f%%</span><span class="se">\t</span><span class="s">%s</span><span class="se">\n</span><span class="s">"</span><span class="p">,</span>
            <span class="n">num</span><span class="p">,</span>
            <span class="n">humanReadableSize</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">jsonData</span><span class="p">)),</span>
            <span class="n">humanReadableSize</span><span class="p">(</span><span class="n">gzippedJsonSize</span><span class="p">),</span>
            <span class="n">jsonReduction</span><span class="p">,</span>
            <span class="n">humanReadableSize</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="n">protData</span><span class="p">)),</span>
            <span class="n">humanReadableSize</span><span class="p">(</span><span class="n">gzippedProtoSize</span><span class="p">),</span>
            <span class="n">protoReduction</span><span class="p">,</span>
            <span class="n">humanReadableSize</span><span class="p">(</span><span class="n">diff</span><span class="p">),</span>
        <span class="p">)</span>
    <span class="p">}</span>
    <span class="n">writer</span><span class="o">.</span><span class="n">Flush</span><span class="p">()</span>
<span class="p">}</span>

<span class="c">// gzipDataAndReturnSize gzips the input data and return the len of the data</span>
<span class="k">func</span> <span class="n">gzipDataAndReturnSize</span><span class="p">(</span><span class="n">data</span> <span class="p">[]</span><span class="kt">byte</span><span class="p">)</span> <span class="kt">int</span> <span class="p">{</span>
    <span class="k">var</span> <span class="n">buf</span> <span class="n">bytes</span><span class="o">.</span><span class="n">Buffer</span>
    <span class="n">gw</span> <span class="o">:=</span> <span class="n">gzip</span><span class="o">.</span><span class="n">NewWriter</span><span class="p">(</span><span class="o">&amp;</span><span class="n">buf</span><span class="p">)</span>
    <span class="n">gw</span><span class="o">.</span><span class="n">Write</span><span class="p">(</span><span class="n">data</span><span class="p">)</span>
    <span class="n">gw</span><span class="o">.</span><span class="n">Close</span><span class="p">()</span>

    <span class="k">return</span> <span class="n">buf</span><span class="o">.</span><span class="n">Len</span><span class="p">()</span>
<span class="p">}</span>

<span class="c">// humanReadableSize returns a human-readable size string.</span>
<span class="c">// e.g. 1024 -&gt; 1 KB</span>
<span class="c">// e.g. 1048576 -&gt; 1 MB</span>
<span class="k">func</span> <span class="n">humanReadableSize</span><span class="p">(</span><span class="n">bytes</span> <span class="kt">int</span><span class="p">)</span> <span class="kt">string</span> <span class="p">{</span>
<span class="p">}</span>

<span class="c">// readUsername returns a array of dummy username</span>
<span class="k">func</span> <span class="n">readUsername</span><span class="p">(</span><span class="n">fileName</span> <span class="kt">string</span><span class="p">)</span> <span class="p">[]</span><span class="kt">string</span> <span class="p">{</span>
<span class="p">}</span>
</code></pre></div></div>

<p class="notice--info">I have intentionally kept only the important parts of the code and removed some not so important code. The full code can be found <a href="https://gist.github.com/saran2020/c2b826b26d83cff3f320c5c60dffd4e2">here</a>.</p>

<p>In the above program, we are creating a list of user objects with fields name, age and email address. We pick a user name at random and use that in the name and email address fields. Once we have the data ready, we marshal them into JSON and proto, and then gzip them and print out the result.</p>

<p>We do this from 1 to 1000000 times with multiples of 10.</p>

<h3 id="result">Result</h3>

<table>
  <tbody>
    <tr>
      <td>Users</td>
      <td>JSON Size</td>
      <td>Gzipped JSON Size</td>
      <td>JSON Gzip size %</td>
      <td>Proto Size</td>
      <td>Gzipped Proto Size</td>
      <td>Proto Gzip size %</td>
      <td>Gzip Diff (JSON - Proto)</td>
    </tr>
    <tr>
      <td>1</td>
      <td>75B</td>
      <td>85B</td>
      <td>113%</td>
      <td>40B</td>
      <td>55B</td>
      <td>138%</td>
      <td>30B</td>
    </tr>
    <tr>
      <td>10</td>
      <td>673B</td>
      <td>232B</td>
      <td>34%</td>
      <td>398B</td>
      <td>216B</td>
      <td>54%</td>
      <td>16B</td>
    </tr>
    <tr>
      <td>100</td>
      <td>6.3KB</td>
      <td>1.4KB</td>
      <td>22%</td>
      <td>3.7KB</td>
      <td>1.4KB</td>
      <td>37%</td>
      <td>12B</td>
    </tr>
    <tr>
      <td>1000</td>
      <td>62.5KB</td>
      <td>11.8KB</td>
      <td>19%</td>
      <td>36.5KB</td>
      <td>12.3KB</td>
      <td>34%</td>
      <td>542B</td>
    </tr>
    <tr>
      <td>10000</td>
      <td>624.9KB</td>
      <td>115.7KB</td>
      <td>19%</td>
      <td>364.3KB</td>
      <td>121.7KB</td>
      <td>33%</td>
      <td>-6.0KB</td>
    </tr>
    <tr>
      <td>100000</td>
      <td>6.1MB</td>
      <td>1.1MB</td>
      <td>18%</td>
      <td>3.6MB</td>
      <td>1.2MB</td>
      <td>33%</td>
      <td>-60.7KB</td>
    </tr>
    <tr>
      <td>1000000</td>
      <td>61.1MB</td>
      <td>11.3MB</td>
      <td>18%</td>
      <td>35.7MB</td>
      <td>11.9MB</td>
      <td>33%</td>
      <td>-603.8KB</td>
    </tr>
  </tbody>
</table>

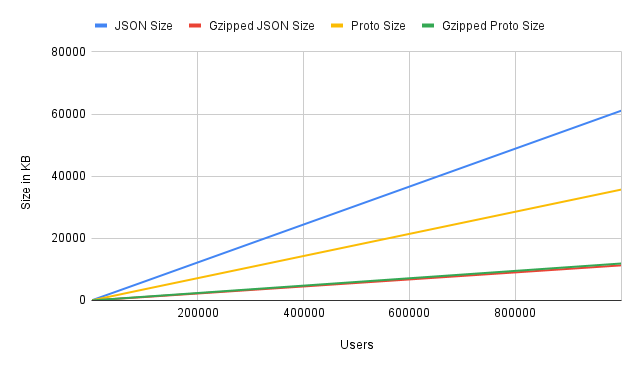
<p><img src="/assets/images/json-vs-proto-gzip.png" alt="" /></p>

<h2 id="observation">Observation</h2>
<ul>
  <li>When we have really small data, the gzipped size increases instead of decreasing. This is because, when data is gzipped it adds some additional metadata which will be used to decompress it. Here these metadata cause the size of the data to increase instead of decrease because the size of the data in itself is less.</li>
  <li>JSON compression is far more efficient than proto as the compressed size ratio is consistently better than protos gzipped data. EG: for 10 users the JSON size is 637B and gzipped size is 226B which is 35% of the original data. But in the same place for proto the gziped size is 37% of the original data.</li>
  <li>As the size of the data increases, the gziped sized of both proto and JSON remains consistent with minor difference.</li>
</ul>

<p class="notice--info">The experiment was conducted for a list of Users. Which will have keys like “Name”, “Age” &amp; “Email” repeated the same number of times as users. This must be making JSON more efficient. The real-world data will be different with limited key repetition thus the results could vary as well.</p>

<h2 id="conclusion">Conclusion</h2>
<p>When we talk about REST vs gRPC in the context of client-server communication, where the client could be a mobile device which could face latency issues. The payload size advantage of gRPC making it faster doesn’t hold true because in today’s day and age gzip has become standard when sending data over the internet. However, there would be several other advantages that gRPC would provide over REST which is a topic for another day.</p>]]></content><author><name>Saran</name></author><category term="gRPC" /><category term="gRPC" /><category term="Networking" /><category term="ProtocolBuffers" /><category term="JSON" /><category term="Compression" /><summary type="html"><![CDATA[A few days back I was debating with a friend about REST vs gRPC in the context of client-server communication over the Internet. Where I was in favour of gRPC. During our debate, I jumped quickly to say protobuf are more optimised than JSON because they omit unwanted data. To which my friend replied that we don’t transfer plain JSON over the network anymore we always gzip them before sending them. He explained further, that all the optimisation that gRPC does is lost when we gzip the data. I couldn’t continue to argue my point because I didn’t have enough data to prove my point. Thus I decided to run an experiment to compare the size after gziping JSON vs Protobuf. Since I was in the process of learning go language from scratch, I decided to use it for this experiment. Code var UserCounts = [...]int{1, 10, 100, 1000, 10000, 100000, 1000000} func main() { names := readUsername(usernamesFile) usersList := UsersProto{ Users: []*UserProto{}, } writer := tabwriter.NewWriter(os.Stdout, 0, 0, 1, ' ', tabwriter.Debug) fmt.Fprintln(writer, "Users\tJSON Size\tGzipped JSON Size\tJSON Gzip size % \tProto Size\tGzipped Proto Size\tProto Gzip size %\tGzip Diff (JSON - Proto)") for _, num := range UserCounts { for i := 0; i &lt; num; i++ { name := names[rand.IntN(len(names))] user := UserProto{ Name: name, Age: rand.Int32N(91) + 10, Email: fmt.Sprintf("%s@gmail.com", name), } usersList.Users = append(usersList.Users, &amp;user) } jsonData, _ := json.Marshal(usersList) protData, _ := proto.Marshal(&amp;usersList) gzippedProtoSize := gzipDataAndReturnSize(protData) gzippedJsonSize := gzipDataAndReturnSize(jsonData) jsonReduction := float64(gzippedJsonSize) / float64(len(jsonData)) * 100 protoReduction := float64(gzippedProtoSize) / float64(len(protData)) * 100 diff := gzippedJsonSize - gzippedProtoSize fmt.Fprintf(writer, "%d\t%s\t%s\t%.0f%%\t%s\t%s\t%.0f%%\t%s\n", num, humanReadableSize(len(jsonData)), humanReadableSize(gzippedJsonSize), jsonReduction, humanReadableSize(len(protData)), humanReadableSize(gzippedProtoSize), protoReduction, humanReadableSize(diff), ) } writer.Flush() } // gzipDataAndReturnSize gzips the input data and return the len of the data func gzipDataAndReturnSize(data []byte) int { var buf bytes.Buffer gw := gzip.NewWriter(&amp;buf) gw.Write(data) gw.Close() return buf.Len() } // humanReadableSize returns a human-readable size string. // e.g. 1024 -&gt; 1 KB // e.g. 1048576 -&gt; 1 MB func humanReadableSize(bytes int) string { } // readUsername returns a array of dummy username func readUsername(fileName string) []string { } I have intentionally kept only the important parts of the code and removed some not so important code. The full code can be found here. In the above program, we are creating a list of user objects with fields name, age and email address. We pick a user name at random and use that in the name and email address fields. Once we have the data ready, we marshal them into JSON and proto, and then gzip them and print out the result. We do this from 1 to 1000000 times with multiples of 10. Result Users JSON Size Gzipped JSON Size JSON Gzip size % Proto Size Gzipped Proto Size Proto Gzip size % Gzip Diff (JSON - Proto) 1 75B 85B 113% 40B 55B 138% 30B 10 673B 232B 34% 398B 216B 54% 16B 100 6.3KB 1.4KB 22% 3.7KB 1.4KB 37% 12B 1000 62.5KB 11.8KB 19% 36.5KB 12.3KB 34% 542B 10000 624.9KB 115.7KB 19% 364.3KB 121.7KB 33% -6.0KB 100000 6.1MB 1.1MB 18% 3.6MB 1.2MB 33% -60.7KB 1000000 61.1MB 11.3MB 18% 35.7MB 11.9MB 33% -603.8KB Observation When we have really small data, the gzipped size increases instead of decreasing. This is because, when data is gzipped it adds some additional metadata which will be used to decompress it. Here these metadata cause the size of the data to increase instead of decrease because the size of the data in itself is less. JSON compression is far more efficient than proto as the compressed size ratio is consistently better than protos gzipped data. EG: for 10 users the JSON size is 637B and gzipped size is 226B which is 35% of the original data. But in the same place for proto the gziped size is 37% of the original data. As the size of the data increases, the gziped sized of both proto and JSON remains consistent with minor difference. The experiment was conducted for a list of Users. Which will have keys like “Name”, “Age” &amp; “Email” repeated the same number of times as users. This must be making JSON more efficient. The real-world data will be different with limited key repetition thus the results could vary as well. Conclusion When we talk about REST vs gRPC in the context of client-server communication, where the client could be a mobile device which could face latency issues. The payload size advantage of gRPC making it faster doesn’t hold true because in today’s day and age gzip has become standard when sending data over the internet. However, there would be several other advantages that gRPC would provide over REST which is a topic for another day.]]></summary></entry><entry><title type="html">Things to keep in mind before chossing gRPC for you mobile app</title><link href="https://saran.sankaran.dev/grpc/Things-to-know-about-grpc-on-mobile/" rel="alternate" type="text/html" title="Things to keep in mind before chossing gRPC for you mobile app" /><published>2024-10-19T05:30:00+05:30</published><updated>2024-10-19T05:30:00+05:30</updated><id>https://saran.sankaran.dev/grpc/Things-to-know-about-grpc-on-mobile</id><content type="html" xml:base="https://saran.sankaran.dev/grpc/Things-to-know-about-grpc-on-mobile/"><![CDATA[<p>Gone are the days when we used to use SOAP for exchanging data between mobile and server. REST has become the default for transferring data between the client and the server. However, there is a new kid in the block which is getting popular: gRPC or Google Remote Procedural Call. Here procedure means a function ie: Google Remote Function Call. So like functions we define, it takes some input parameters and does some processing on it and then returns a response. gRPC is nothing novel, but pretty basic. We create a contract of what will be sent from one end and received on the other end using a <code class="language-plaintext highlighter-rouge">.proto</code> file. Then we send the actual message as bytes based on the defined contract.</p>

<p>Example <code class="language-plaintext highlighter-rouge">helloworld.proto</code></p>
<div class="language-proto highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">syntax</span> <span class="o">=</span> <span class="s">"proto3"</span><span class="p">;</span>

<span class="k">option</span> <span class="na">java_package</span> <span class="o">=</span> <span class="s">"io.grpc.examples.helloworld"</span><span class="p">;</span>

<span class="kn">package</span> <span class="nn">helloworld</span><span class="p">;</span>

<span class="c1">// The greeting service definition.</span>
<span class="kd">service</span> <span class="n">Greeter</span> <span class="p">{</span>
 <span class="c1">// Sends a greeting</span>
 <span class="k">rpc</span> <span class="n">SayHello</span> <span class="p">(</span><span class="n">HelloRequest</span><span class="p">)</span> <span class="k">returns</span> <span class="p">(</span><span class="n">HelloReply</span><span class="p">)</span> <span class="p">{}</span>
<span class="p">}</span>

<span class="o">/</span> <span class="n">The</span> <span class="n">request</span> <span class="kd">message</span> <span class="nc">containing</span> <span class="n">the</span> <span class="n">user</span><span class="err">'</span><span class="n">s</span> <span class="n">name.</span>
<span class="kd">message</span> <span class="nc">HelloRequest</span> <span class="p">{</span>
 <span class="kt">string</span> <span class="na">name</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span>
<span class="p">}</span>

<span class="c1">// The response message containing the greetings</span>
<span class="kd">message</span> <span class="nc">HelloReply</span> <span class="p">{</span>
 <span class="kt">string</span> <span class="kd">message</span> <span class="o">=</span> <span class="mi">1</span><span class="p">;</span>
 <span class="kt">int32</span> <span class="na">message_length</span> <span class="o">=</span> <span class="mi">2</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Here we are defining 1 API call named <code class="language-plaintext highlighter-rouge">SayHello</code>. We need to provide the <code class="language-plaintext highlighter-rouge">HelloRequest</code> as input to this API and <code class="language-plaintext highlighter-rouge">HelloReply</code> is what is returned from the API.</p>

<p><code class="language-plaintext highlighter-rouge">HelloRequest</code> has a <code class="language-plaintext highlighter-rouge">name</code> field in it of type String.</p>

<p><code class="language-plaintext highlighter-rouge">HelloReply</code> has a <code class="language-plaintext highlighter-rouge">message</code> field in it of type String, and also <code class="language-plaintext highlighter-rouge">message_length</code> of type int.</p>

<p>Additionally, we would also use a protobuf plugin to generate the Models for the Request and Responses and Stubs for the RPC call, in different languages like Java, Python, Go, C++ or Objective C. Now when the server implements the <code class="language-plaintext highlighter-rouge">SayHello</code> rpc, and a client makes a call to this rpc with the <code class="language-plaintext highlighter-rouge">HelloRequest</code> using the stub generated by the protobuff plugin, the server will return a <code class="language-plaintext highlighter-rouge">HelloReply</code> response.</p>

<p>The generated code can be quite a lot for mobile clients, thus the Protbuff plugin 2 options: Regular and Protobuf-lite. Regular is meant to be used by servers where it’s ok to generate a little extra code without much cost. On mobile, generating a lot of code will quickly add up, since Classloader will have to load all this extra class. Also, it will increase the App download size significantly. Thus on mobile, it’s recommended to use protobuf-lite version, which generates relatively lesser code.</p>

<h2 id="pros-of-using-grpc-for-mobile-apps">Pros of using gRPC for mobile apps</h2>
<ul>
  <li>Reduced network bandwidth when compared to REST is significantly lesser because when using data types like JSON, there is no pre-defined contract between Server and Client. This means, the messages transmitted need to include a key, which says what data we are passing and the actual data. EG name: “Saran”. Here <code class="language-plaintext highlighter-rouge">name</code> is the key and “Saran” is the value. Whereas the client only needs the value “Saran”. Which causes increased response size. While in gRPC, since the contract is formally defined as a protobuf file, only the actual value needs to be transmitted.</li>
  <li>Clearly defined contracts, which means communication between the Backend team and Client team is efficient, and there is no scope for miscommunication. Whereas, in REST this contract is not formally defined, which means the client and server can have different understandings of them.</li>
  <li>Support for unidirectional and multi-directional streaming. Which is often required when we have to upload files or continuously stream data like stock prices from the server.</li>
</ul>

<h2 id="cons-of-using-grpc-for-mobile">Cons of using grpc for mobile</h2>
<ul>
  <li>Increased App size in the long run. This is because even if use protobuf-lite it still generates a lot of code, whereas libraries like Retrofit in combination with gSON or Moshi make things a lot more efficient when using REST.</li>
  <li>Lack of resources and tooling support. When compared to REST which has gotten mature over time, especially on the client side there is an ample amount of resources and tooling which makes debugging or solving a complex challenge easier. However, since gRPC is new there are fewer resources and tools. Also, since gRPC is protobuf based all the tools need the .proto file to understand the request and response which only adds complexity to the tooling support.</li>
  <li>Rigid: Because gRPC is protbuf-based, the contracts are very strict and it’s not easy to make new changes. To change, we have to update the proto file, generate both client and server codes from the proto file and then implement them. This is time-consuming.</li>
</ul>

<h2 id="conclusion">Conclusion</h2>
<p>Yes, gRPC is great for mobile apps especially due to the reduced transmission size of data. Reduced data to be transmitted means, faster transfer even when on slow internet. However, we still need better tooling support for gRPC because without them debugging becomes very difficult. Whereas tools like Stetho by Facebook makes debugging network calls as easy as a breeze.</p>]]></content><author><name>Saran</name></author><category term="gRPC" /><category term="gRPC" /><category term="Networking" /><category term="ProtocolBuffers" /><summary type="html"><![CDATA[Gone are the days when we used to use SOAP for exchanging data between mobile and server. REST has become the default for transferring data between the client and the server. However, there is a new kid in the block which is getting popular: gRPC or Google Remote Procedural Call. Here procedure means a function ie: Google Remote Function Call. So like functions we define, it takes some input parameters and does some processing on it and then returns a response. gRPC is nothing novel, but pretty basic. We create a contract of what will be sent from one end and received on the other end using a .proto file. Then we send the actual message as bytes based on the defined contract. Example helloworld.proto syntax = "proto3"; option java_package = "io.grpc.examples.helloworld"; package helloworld; // The greeting service definition. service Greeter { // Sends a greeting rpc SayHello (HelloRequest) returns (HelloReply) {} } / The request message containing the user's name. message HelloRequest { string name = 1; } // The response message containing the greetings message HelloReply { string message = 1; int32 message_length = 2; } Here we are defining 1 API call named SayHello. We need to provide the HelloRequest as input to this API and HelloReply is what is returned from the API. HelloRequest has a name field in it of type String. HelloReply has a message field in it of type String, and also message_length of type int. Additionally, we would also use a protobuf plugin to generate the Models for the Request and Responses and Stubs for the RPC call, in different languages like Java, Python, Go, C++ or Objective C. Now when the server implements the SayHello rpc, and a client makes a call to this rpc with the HelloRequest using the stub generated by the protobuff plugin, the server will return a HelloReply response. The generated code can be quite a lot for mobile clients, thus the Protbuff plugin 2 options: Regular and Protobuf-lite. Regular is meant to be used by servers where it’s ok to generate a little extra code without much cost. On mobile, generating a lot of code will quickly add up, since Classloader will have to load all this extra class. Also, it will increase the App download size significantly. Thus on mobile, it’s recommended to use protobuf-lite version, which generates relatively lesser code. Pros of using gRPC for mobile apps Reduced network bandwidth when compared to REST is significantly lesser because when using data types like JSON, there is no pre-defined contract between Server and Client. This means, the messages transmitted need to include a key, which says what data we are passing and the actual data. EG name: “Saran”. Here name is the key and “Saran” is the value. Whereas the client only needs the value “Saran”. Which causes increased response size. While in gRPC, since the contract is formally defined as a protobuf file, only the actual value needs to be transmitted. Clearly defined contracts, which means communication between the Backend team and Client team is efficient, and there is no scope for miscommunication. Whereas, in REST this contract is not formally defined, which means the client and server can have different understandings of them. Support for unidirectional and multi-directional streaming. Which is often required when we have to upload files or continuously stream data like stock prices from the server. Cons of using grpc for mobile Increased App size in the long run. This is because even if use protobuf-lite it still generates a lot of code, whereas libraries like Retrofit in combination with gSON or Moshi make things a lot more efficient when using REST. Lack of resources and tooling support. When compared to REST which has gotten mature over time, especially on the client side there is an ample amount of resources and tooling which makes debugging or solving a complex challenge easier. However, since gRPC is new there are fewer resources and tools. Also, since gRPC is protobuf based all the tools need the .proto file to understand the request and response which only adds complexity to the tooling support. Rigid: Because gRPC is protbuf-based, the contracts are very strict and it’s not easy to make new changes. To change, we have to update the proto file, generate both client and server codes from the proto file and then implement them. This is time-consuming. Conclusion Yes, gRPC is great for mobile apps especially due to the reduced transmission size of data. Reduced data to be transmitted means, faster transfer even when on slow internet. However, we still need better tooling support for gRPC because without them debugging becomes very difficult. Whereas tools like Stetho by Facebook makes debugging network calls as easy as a breeze.]]></summary></entry><entry><title type="html">How we implemented a better approach than certificate transparency and pinning</title><link href="https://saran.sankaran.dev/tls/How-we-implemented-a-better-approach-than-certificate-transparency-and-pinning/" rel="alternate" type="text/html" title="How we implemented a better approach than certificate transparency and pinning" /><published>2024-09-28T05:30:00+05:30</published><updated>2024-09-28T05:30:00+05:30</updated><id>https://saran.sankaran.dev/tls/How-we-implemented-a-better-approach-than-certificate-transparency-and-pinning</id><content type="html" xml:base="https://saran.sankaran.dev/tls/How-we-implemented-a-better-approach-than-certificate-transparency-and-pinning/"><![CDATA[<p>A few days ago I was reading <a href="https://blog.cloudflare.com/why-certificate-pinning-is-outdated/">this</a> article by Cloudflare which brought back some memories of how we dealt with the issue of certificate pinning on Android. It motivated me to write this blog about how we implemented a hybrid approach which is fast and secure at the same time. While also sharing the drawbacks of each approach.</p>

<p>Before we begin, I want you to remember that the Fi app uses GRPC as its core network stack. However, these solutions can be applied to other types of network calls as well. However, the implementation steps may vary.</p>

<p>With Vanilla TLS, it’s easy to do a Man In The Middle (MITM) attack. Thus we wanted something stronger than that.</p>

<h3 id="certificate-transparency-ct">Certificate Transparency (CT)</h3>
<p>Certificate Transparency is an additional step performed over the standard TLS verification, like verifying the Hostname name and root CA etc. When Certificate Transparency is performed, it makes a network call to a separate log server with the Signed Certificate Timestamp (SCT) embedded in the certificate.</p>

<p class="notice--info">You can learn how certificate transparency works <a href="https://certificate.transparency.dev/howctworks/">here</a>.</p>

<p>Fi also being a payments app, people would use the app at the storefront to make payments. The internet connectivity here would likely be very flaky or poor. In such cases making any additional calls on the network leads to extra time taken in app launch. After doing a lot of analysis, we found that CT was adding up to an extra 2 seconds even before a connection was established with the server.</p>

<p>Thus we started looking for something more efficient while also secure. That’s how we decided to try certificate pinning.</p>

<h3 id="certificate-pinning-pinning">Certificate Pinning (Pinning)</h3>
<p class="notice--info">Most of the time when we pin, we are not pinning the certificate itself, but the hash of the public key, found in the certificate. The advantage here is that we can rotate the certificate but may keep the public key the same. However, this is not recommended. Thus the name Certificate Pinning is incorrect and should have been Public Key pinning.</p>

<p>We pinned the public key using a network security config. Which is the recommended way to do it according to Android’s <a href="https://developer.android.com/privacy-and-security/security-config#CertificatePinning">docs</a>.</p>

<p>Whenever we do pinning, it always comes at the cost of flexibility. The flexibility to change the public key before the expiry of the certificate or unexpected leak of the private key.</p>

<p>Because the certificate rotation bit is very complex. If we miss any step during key rotation, then we block several users out of the app. Since pinning is also done within an XML file, it doesn’t allow us to implement any logic. These were some of the big factors for us not to go with just vanilla pinning. This made us look for alternatives.</p>

<h3 id="hybrid-approach">Hybrid approach</h3>
<p>We came up with a hybrid approach that combined both CT and pinning. The drawback of CT is that it was slow, but flexible in terms of certificate rotation. The problem with pinning is that it’s faster even when on a slow network but not flexible when rotating the keys. Thus we combined both to get the goodness of each.</p>

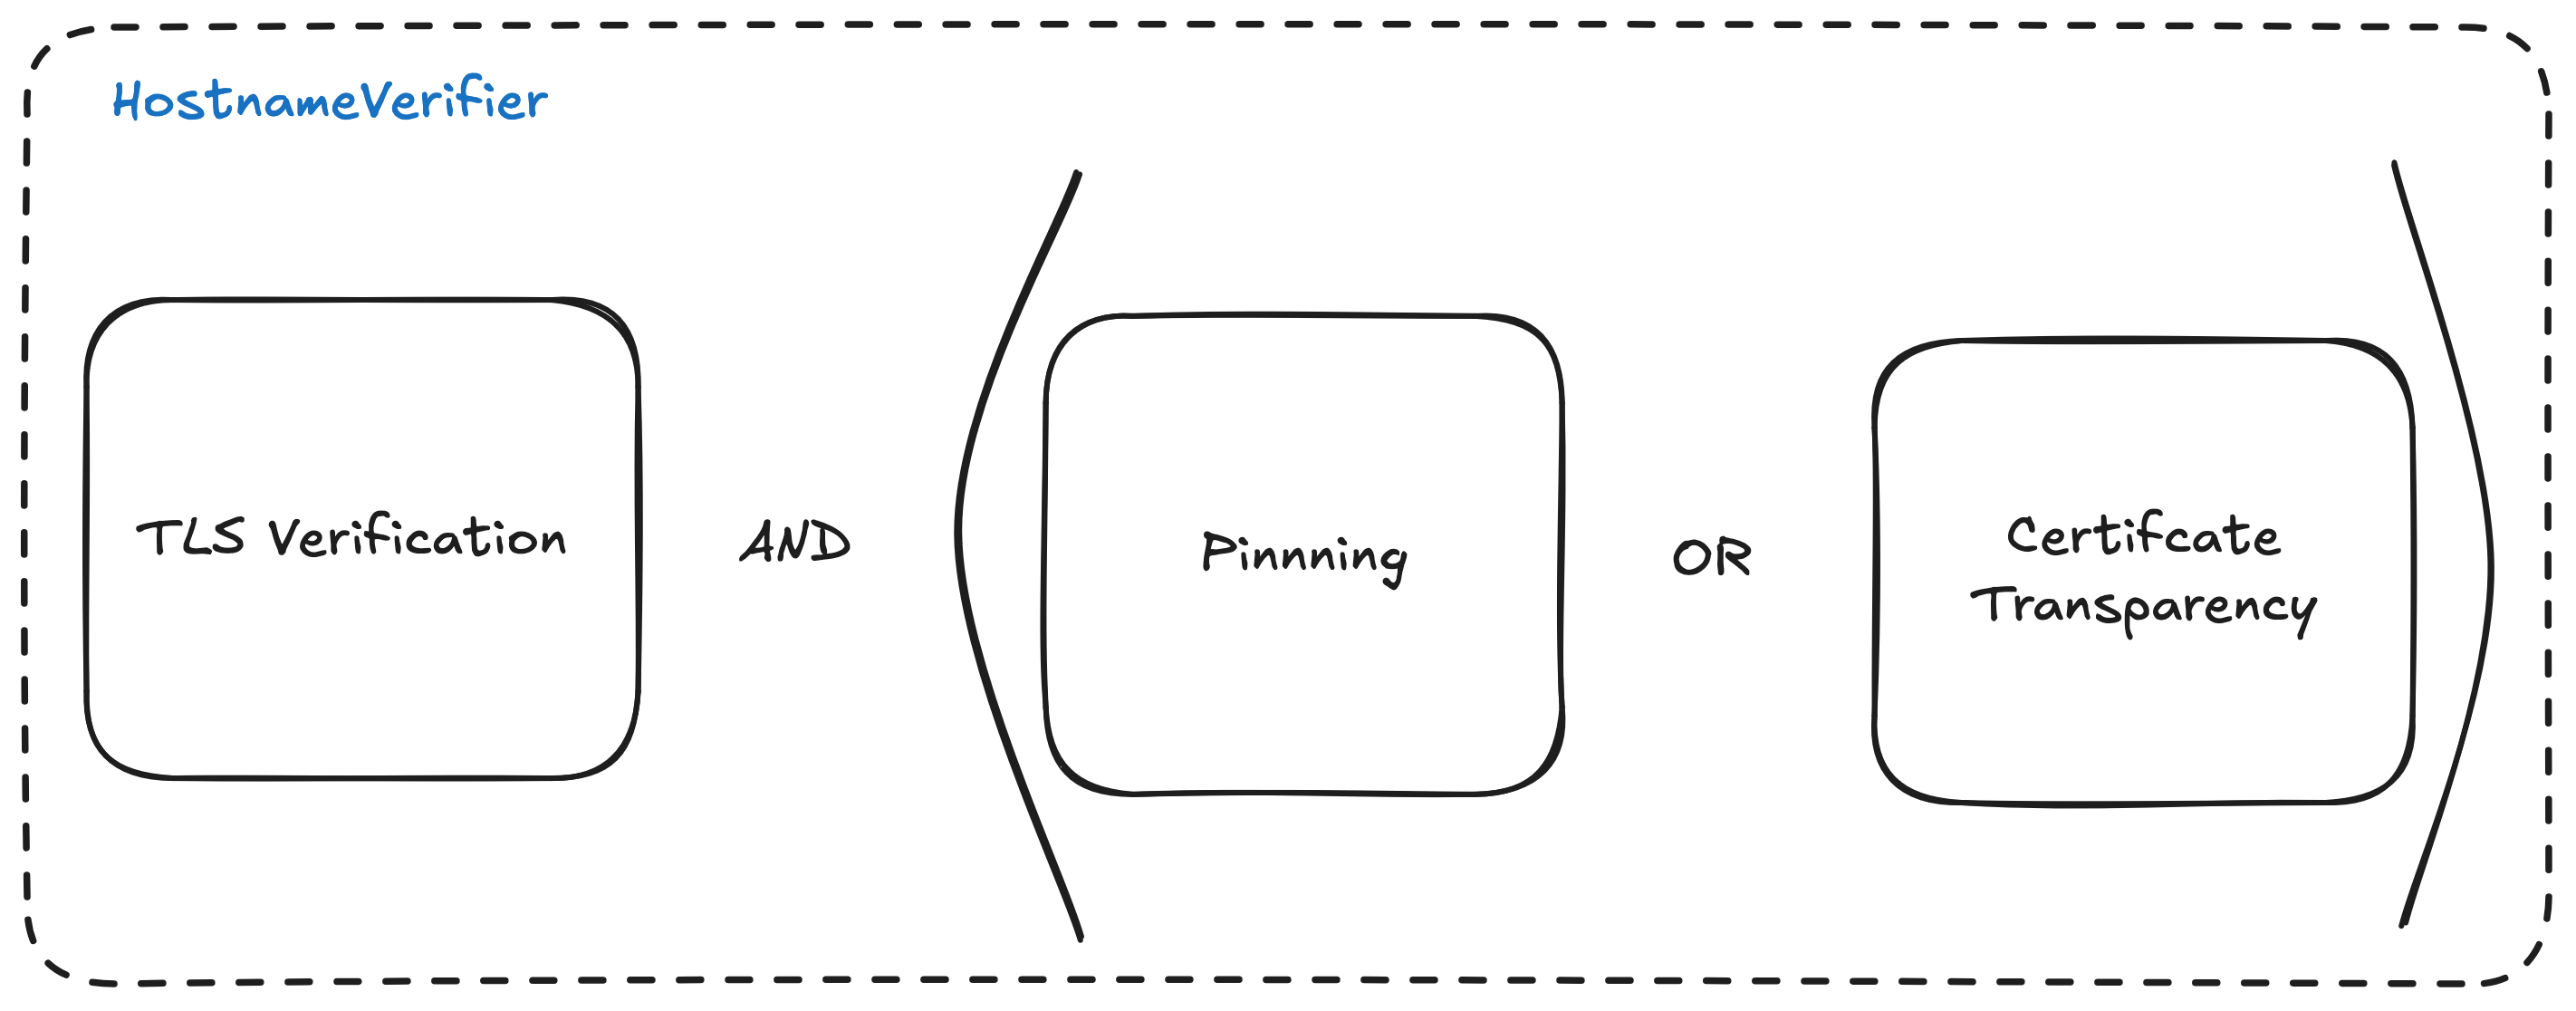
<p>We implemented a mechanism in our <code class="language-plaintext highlighter-rouge">HostNameVerifier</code> where firstly we did the traditional check performed by TLS and then verified the pins. This would pass in most of the cases. However, when we have just rotated the certificate, the older app versions with older pins will fail the pinning check. When it fails, we fall back to CT to verify the certificate, over the network. This is also effective in blocking the unsolicited MITM attacks.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">internal</span> <span class="kd">class</span> <span class="nc">PinningOrCertificateTransparencyHostNameVerifier</span><span class="p">(</span>
    <span class="k">private</span> <span class="kd">val</span> <span class="py">pins</span><span class="p">:</span> <span class="nc">Map</span><span class="p">&lt;</span><span class="nc">Host</span><span class="p">,</span> <span class="nc">Set</span><span class="p">&lt;</span><span class="nc">PublicKeySha256</span><span class="p">&gt;&gt;,</span>
    <span class="k">private</span> <span class="kd">val</span> <span class="py">certificateTransparencyHostNameVerifier</span><span class="p">:</span> <span class="nc">HostnameVerifier</span>
<span class="p">)</span> <span class="p">:</span> <span class="nc">HostnameVerifier</span> <span class="p">{</span>

    <span class="nd">@SuppressLint</span><span class="p">(</span><span class="s">"BadHostnameVerifier"</span><span class="p">)</span>
    <span class="k">override</span> <span class="k">fun</span> <span class="nf">verify</span><span class="p">(</span><span class="n">hostname</span><span class="p">:</span> <span class="nc">String</span><span class="p">,</span> <span class="n">session</span><span class="p">:</span> <span class="nc">SSLSession</span><span class="p">):</span> <span class="nc">Boolean</span> <span class="p">{</span>
        <span class="c1">// We should call verifyOkHostname first and if it passes</span>
        <span class="c1">// call pinning first or certificate transparency either has to return true</span>
        <span class="c1">// for the connection to be considered secure.</span>
        <span class="k">return</span> <span class="nf">verifyOkHostname</span><span class="p">(</span><span class="n">hostname</span><span class="p">,</span> <span class="n">session</span><span class="p">)</span>
            <span class="p">&amp;&amp;</span> <span class="p">(</span><span class="nf">verifyPublicKeyPinning</span><span class="p">(</span><span class="n">hostname</span><span class="p">,</span> <span class="n">session</span><span class="p">)</span>
            <span class="p">||</span> <span class="nf">verifyCertificateTransparency</span><span class="p">(</span><span class="n">hostname</span><span class="p">,</span> <span class="n">session</span><span class="p">))</span>
    <span class="p">}</span>

    <span class="k">private</span> <span class="k">fun</span> <span class="nf">verifyOkHostname</span><span class="p">(</span><span class="n">hostname</span><span class="p">:</span> <span class="nc">String</span><span class="p">,</span> <span class="n">session</span><span class="p">:</span> <span class="nc">SSLSession</span><span class="p">):</span> <span class="nc">Boolean</span> <span class="p">{</span>
        <span class="kd">val</span> <span class="py">okHttpResult</span> <span class="p">=</span> <span class="nc">OkHostnameVerifier</span><span class="p">.</span><span class="nf">verify</span><span class="p">(</span><span class="n">hostname</span><span class="p">,</span> <span class="n">session</span><span class="p">)</span>
        <span class="nc">Timber</span><span class="p">.</span><span class="nf">i</span><span class="p">(</span><span class="s">"OkHostnameVerifier result: $okHttpResult"</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">okHttpResult</span>
    <span class="p">}</span>

    <span class="k">private</span> <span class="k">fun</span> <span class="nf">verifyPublicKeyPinning</span><span class="p">(</span><span class="n">hostname</span><span class="p">:</span> <span class="nc">String</span><span class="p">,</span> <span class="n">session</span><span class="p">:</span> <span class="nc">SSLSession</span><span class="p">):</span> <span class="nc">Boolean</span> <span class="p">{</span>
        <span class="c1">// We try and find a pin for the hostname, else return false</span>
        <span class="kd">val</span> <span class="py">setOfPins</span> <span class="p">=</span> <span class="n">pins</span><span class="p">[</span><span class="nc">Host</span><span class="p">(</span><span class="n">hostname</span><span class="p">)]</span> <span class="o">?:</span> <span class="n">kotlin</span><span class="p">.</span><span class="nf">run</span> <span class="p">{</span>
            <span class="nc">Timber</span><span class="p">.</span><span class="nf">w</span><span class="p">(</span><span class="s">"No pin found for $hostname"</span><span class="p">)</span>
            <span class="k">return</span> <span class="k">false</span>
        <span class="p">}</span>
        <span class="kd">val</span> <span class="py">leafCertificate</span><span class="p">:</span> <span class="nc">Certificate</span> <span class="p">=</span> <span class="n">session</span><span class="p">.</span><span class="n">peerCertificates</span><span class="p">[</span><span class="mi">0</span><span class="p">]</span>
        <span class="kd">val</span> <span class="py">sha256</span><span class="p">:</span> <span class="nc">String</span> <span class="p">=</span> <span class="n">leafCertificate</span><span class="p">.</span><span class="n">publicKey</span><span class="p">.</span><span class="n">encoded</span><span class="p">.</span><span class="nf">sha256String</span><span class="p">()</span>
        <span class="kd">val</span> <span class="py">pin</span> <span class="p">=</span> <span class="nc">PublicKeySha256</span><span class="p">(</span><span class="n">sha256</span><span class="p">)</span>
        <span class="kd">val</span> <span class="py">isPinVerificationSuccessful</span> <span class="p">=</span> <span class="n">setOfPins</span><span class="p">.</span><span class="nf">contains</span><span class="p">(</span><span class="n">pin</span><span class="p">)</span>
        <span class="nc">Timber</span><span class="p">.</span><span class="nf">i</span><span class="p">(</span><span class="s">"VerifyPublicKeyPinning result: $isPinVerificationSuccessful"</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">isPinVerificationSuccessful</span>
    <span class="p">}</span>

    <span class="k">private</span> <span class="k">fun</span> <span class="nf">verifyCertificateTransparency</span><span class="p">(</span><span class="n">hostname</span><span class="p">:</span> <span class="nc">String</span><span class="p">,</span> <span class="n">session</span><span class="p">:</span> <span class="nc">SSLSession</span><span class="p">):</span> <span class="nc">Boolean</span> <span class="p">{</span>
        <span class="kd">val</span> <span class="py">ctResult</span> <span class="p">=</span> <span class="n">certificateTransparencyHostNameVerifier</span><span class="p">.</span><span class="nf">verify</span><span class="p">(</span><span class="n">hostname</span><span class="p">,</span> <span class="n">session</span><span class="p">)</span>
        <span class="nc">Timber</span><span class="p">.</span><span class="nf">i</span><span class="p">(</span><span class="s">"CertificateTransparency result: $ctResult"</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">ctResult</span>
    <span class="p">}</span>
<span class="p">}</span>

<span class="nd">@JvmInline</span>
<span class="k">internal</span> <span class="n">value</span> <span class="kd">class</span> <span class="nc">Host</span><span class="p">(</span><span class="kd">val</span> <span class="py">host</span><span class="p">:</span> <span class="nc">String</span><span class="p">)</span>

<span class="nd">@JvmInline</span>
<span class="k">internal</span> <span class="n">value</span> <span class="kd">class</span> <span class="nc">PublicKeySha256</span><span class="p">(</span><span class="kd">val</span> <span class="py">pin</span><span class="p">:</span> <span class="nc">String</span><span class="p">)</span>
</code></pre></div></div>

<figure class="align-center">
  <img src="/assets/images/hybrid_verification.png" alt="Hybrid verification" style="width:100%;height:100%;" />
</figure>

<p>This of course comes with some drawbacks</p>
<ol>
  <li>An app would make many different forms of connection in different areas of the app. Eg: We make the API call to load the page, which shows a Terms and Conditions hyperlink. When clicked on it, it opens a web view which shows the Terms and conditions. Here we are making a REST API call to load the page and then loading a Webpage, which will form its new connection to the server even when the endpoints remain the same. In such cases having a centralised place like the Android’s recommended way of pinning would be the best. Since it will verify the same pin for any connection established to the domain by the app. However, when we use the hybrid approach, the code to verify the pin lives within a <code class="language-plaintext highlighter-rouge">HostNameVerifier</code>, which we will have to individually apply on any new connection established by the app.</li>
  <li>When the certificate is rotated, older versions of the app will fall back to CT. The users who are accustomed to the shorter load time will see this increased load time, which is not an ideal experience for any user. However, once in the app, we can nudge them to update the app to the latest version with pins for new certificate.</li>
</ol>

<h3 id="summary">Summary</h3>
<ul>
  <li>Certificate Transparency
    <ul>
      <li>Pro
        <ol>
          <li>No extra handling is needed when the certificate is rotated, as some verification happens on the network.</li>
        </ol>
      </li>
      <li>Con
        <ol>
          <li>Very slow when on an unstable internet connection</li>
        </ol>
      </li>
    </ul>
  </li>
  <li>Certificate pinning or public key pinning
    <ul>
      <li>Pro
        <ol>
          <li>Faster than CT as all the checks are performed locally on the device.</li>
          <li>Can be configured in one place and it will take effect across the app.</li>
        </ol>
      </li>
      <li>Con
        <ol>
          <li>Very tricky to rotate the certificate. If not planned and executed properly We might lock some or all users out of the app forever.</li>
        </ol>
      </li>
    </ul>
  </li>
  <li>Hybrid Approach (Combination of pinning and CT)
    <ul>
      <li>Pro
        <ol>
          <li>Speedy verification of pinned certificate</li>
          <li>Gets the flexibility of CT when certificates are rotated</li>
        </ol>
      </li>
      <li>Con
        <ol>
          <li>Cannot be configured centrally in one place</li>
          <li>Takes time to establish the connection as pin verifications will fail and it will fall back to CT.</li>
        </ol>
      </li>
    </ul>
  </li>
</ul>]]></content><author><name>Saran</name></author><category term="TLS" /><category term="TLS" /><category term="SSL" /><category term="HostnameVerifier" /><summary type="html"><![CDATA[A few days ago I was reading this article by Cloudflare which brought back some memories of how we dealt with the issue of certificate pinning on Android. It motivated me to write this blog about how we implemented a hybrid approach which is fast and secure at the same time. While also sharing the drawbacks of each approach. Before we begin, I want you to remember that the Fi app uses GRPC as its core network stack. However, these solutions can be applied to other types of network calls as well. However, the implementation steps may vary. With Vanilla TLS, it’s easy to do a Man In The Middle (MITM) attack. Thus we wanted something stronger than that. Certificate Transparency (CT) Certificate Transparency is an additional step performed over the standard TLS verification, like verifying the Hostname name and root CA etc. When Certificate Transparency is performed, it makes a network call to a separate log server with the Signed Certificate Timestamp (SCT) embedded in the certificate. You can learn how certificate transparency works here. Fi also being a payments app, people would use the app at the storefront to make payments. The internet connectivity here would likely be very flaky or poor. In such cases making any additional calls on the network leads to extra time taken in app launch. After doing a lot of analysis, we found that CT was adding up to an extra 2 seconds even before a connection was established with the server. Thus we started looking for something more efficient while also secure. That’s how we decided to try certificate pinning. Certificate Pinning (Pinning) Most of the time when we pin, we are not pinning the certificate itself, but the hash of the public key, found in the certificate. The advantage here is that we can rotate the certificate but may keep the public key the same. However, this is not recommended. Thus the name Certificate Pinning is incorrect and should have been Public Key pinning. We pinned the public key using a network security config. Which is the recommended way to do it according to Android’s docs. Whenever we do pinning, it always comes at the cost of flexibility. The flexibility to change the public key before the expiry of the certificate or unexpected leak of the private key. Because the certificate rotation bit is very complex. If we miss any step during key rotation, then we block several users out of the app. Since pinning is also done within an XML file, it doesn’t allow us to implement any logic. These were some of the big factors for us not to go with just vanilla pinning. This made us look for alternatives. Hybrid approach We came up with a hybrid approach that combined both CT and pinning. The drawback of CT is that it was slow, but flexible in terms of certificate rotation. The problem with pinning is that it’s faster even when on a slow network but not flexible when rotating the keys. Thus we combined both to get the goodness of each. We implemented a mechanism in our HostNameVerifier where firstly we did the traditional check performed by TLS and then verified the pins. This would pass in most of the cases. However, when we have just rotated the certificate, the older app versions with older pins will fail the pinning check. When it fails, we fall back to CT to verify the certificate, over the network. This is also effective in blocking the unsolicited MITM attacks. internal class PinningOrCertificateTransparencyHostNameVerifier( private val pins: Map&lt;Host, Set&lt;PublicKeySha256&gt;&gt;, private val certificateTransparencyHostNameVerifier: HostnameVerifier ) : HostnameVerifier { @SuppressLint("BadHostnameVerifier") override fun verify(hostname: String, session: SSLSession): Boolean { // We should call verifyOkHostname first and if it passes // call pinning first or certificate transparency either has to return true // for the connection to be considered secure. return verifyOkHostname(hostname, session) &amp;&amp; (verifyPublicKeyPinning(hostname, session) || verifyCertificateTransparency(hostname, session)) } private fun verifyOkHostname(hostname: String, session: SSLSession): Boolean { val okHttpResult = OkHostnameVerifier.verify(hostname, session) Timber.i("OkHostnameVerifier result: $okHttpResult") return okHttpResult } private fun verifyPublicKeyPinning(hostname: String, session: SSLSession): Boolean { // We try and find a pin for the hostname, else return false val setOfPins = pins[Host(hostname)] ?: kotlin.run { Timber.w("No pin found for $hostname") return false } val leafCertificate: Certificate = session.peerCertificates[0] val sha256: String = leafCertificate.publicKey.encoded.sha256String() val pin = PublicKeySha256(sha256) val isPinVerificationSuccessful = setOfPins.contains(pin) Timber.i("VerifyPublicKeyPinning result: $isPinVerificationSuccessful") return isPinVerificationSuccessful } private fun verifyCertificateTransparency(hostname: String, session: SSLSession): Boolean { val ctResult = certificateTransparencyHostNameVerifier.verify(hostname, session) Timber.i("CertificateTransparency result: $ctResult") return ctResult } } @JvmInline internal value class Host(val host: String) @JvmInline internal value class PublicKeySha256(val pin: String) This of course comes with some drawbacks An app would make many different forms of connection in different areas of the app. Eg: We make the API call to load the page, which shows a Terms and Conditions hyperlink. When clicked on it, it opens a web view which shows the Terms and conditions. Here we are making a REST API call to load the page and then loading a Webpage, which will form its new connection to the server even when the endpoints remain the same. In such cases having a centralised place like the Android’s recommended way of pinning would be the best. Since it will verify the same pin for any connection established to the domain by the app. However, when we use the hybrid approach, the code to verify the pin lives within a HostNameVerifier, which we will have to individually apply on any new connection established by the app. When the certificate is rotated, older versions of the app will fall back to CT. The users who are accustomed to the shorter load time will see this increased load time, which is not an ideal experience for any user. However, once in the app, we can nudge them to update the app to the latest version with pins for new certificate. Summary Certificate Transparency Pro No extra handling is needed when the certificate is rotated, as some verification happens on the network. Con Very slow when on an unstable internet connection Certificate pinning or public key pinning Pro Faster than CT as all the checks are performed locally on the device. Can be configured in one place and it will take effect across the app. Con Very tricky to rotate the certificate. If not planned and executed properly We might lock some or all users out of the app forever. Hybrid Approach (Combination of pinning and CT) Pro Speedy verification of pinned certificate Gets the flexibility of CT when certificates are rotated Con Cannot be configured centrally in one place Takes time to establish the connection as pin verifications will fail and it will fall back to CT.]]></summary></entry><entry><title type="html">Why nested LazyColumn is not allowed in compose and some solutions you should try</title><link href="https://saran.sankaran.dev/compose/android/Why-nested-LazyColumn-is-not-allowed-in-compose-and-some-solutions-you-should-try/" rel="alternate" type="text/html" title="Why nested LazyColumn is not allowed in compose and some solutions you should try" /><published>2024-07-01T05:30:00+05:30</published><updated>2024-07-01T05:30:00+05:30</updated><id>https://saran.sankaran.dev/compose/android/Why-nested-LazyColumn-is-not-allowed-in-compose-and-some-solutions-you-should-try</id><content type="html" xml:base="https://saran.sankaran.dev/compose/android/Why-nested-LazyColumn-is-not-allowed-in-compose-and-some-solutions-you-should-try/"><![CDATA[<p>Implementing nested lists is a common requirement in many applications, which we have traditionally managed using <code class="language-plaintext highlighter-rouge">RecyclerView</code>. However, in Jetpack Compose, attempting nested <code class="language-plaintext highlighter-rouge">LazyColumn</code> or <code class="language-plaintext highlighter-rouge">LazyRow</code> can lead to the following crash.</p>

<p class="notice--danger"><strong>Exception:</strong>
java.lang.IllegalStateException: Vertically scrollable component was measured with an infinity maximum height constraints, which is disallowed. One of the common reasons is nesting layouts like LazyColumn and Column(Modifier.verticalScroll()). If you want to add a header before the list of items please add a header as a separate item() before the main items() inside the LazyColumn scope. There are could be other reasons for this to happen: your ComposeView was added into a LinearLayout with some weight, you applied Modifier.wrapContentSize(unbounded = true) or wrote a custom layout. Please try to remove the source of infinite constraints in the hierarchy above the scrolling container.</p>

<p>Now let’s try to understand the issue here. LazyColumns by default have an infinite maximum height because they lazy-load items. Due of this nature, it cannot determine its height and thus uses an infinite as its height. Also, since LazyColumns are scrollable, it needs to keep track of the items visible on the screen. When an item is scrolled out of the screen, a new item gets added. Now since the internal LazyColum’s height is infinity, it disrupts the outer LazyColumn from knowing its child’s actual height. This is why we are not allowed to nest LazyColumns.</p>

<p>Now that we understand the problem, let’s look what solutions are avilable to us.</p>

<h5 id="1-flatten-the-list">1. Flatten the list</h5>
<p>One way to solve the nesting of LazyColumns is to flatten the list, such that we can get rid of the internal LazyColumn. This way we will have only 1 lazy column which solves the problem.</p>
<h3 id="pro">Pro</h3>
<ul>
  <li>Solves the LazyColumn issue without adding any new components.</li>
</ul>

<h3 id="con">Con</h3>
<ul>
  <li>Loses data hierarchy. EG: If we are building a feed like Facebook, where we have a post and 2 comments on the post and then the next post. If the user likes a comment, then we can’t immediately identify which post the comment belongs to because our list is flattened.</li>
</ul>

<h5 id="2-compute-the-height-of-the-nested-lazycolumn">2. Compute the height of the nested LazyColumn</h5>
<p>As we found earlier, the infinite height of the LazyColumn is the root cause of the issue. This is understandable as there would be different-sized elements loaded into the LazyColumn. However, this is not the case always. For example, we are building a contacts app or a simple calendar events list. Here the height of the component redered by the list remains consistent. In such cases, we can compute the height of our list in <code class="language-plaintext highlighter-rouge">dp</code> and set it as the height of our inner LazyColumn. This caused, the height of the list nit be infinite and which solves the problem.</p>

<p>EG: The height of 1 item in the nested list is of <code class="language-plaintext highlighter-rouge">40.dp</code> and the list has 10 items. It means we can set the height of the LazyColumn to 40 * 10 = <code class="language-plaintext highlighter-rouge">400.dp</code></p>

<h3 id="pro-1">Pro</h3>
<ul>
  <li>Unlike a flattened list, the hierarchy is still maintained.</li>
</ul>

<h3 id="con-1">Con</h3>
<ul>
  <li>Computing the expected height can be challenging depending on the data rendered by the composable functions.</li>
</ul>

<h5 id="3-setting-max-height">3. Setting max height</h5>
<p>If you have worked with Veiws before there is an attribute <code class="language-plaintext highlighter-rouge">android:maxWidth</code> &amp; <code class="language-plaintext highlighter-rouge">android:maxHeight</code>. The purpose of this is to set the content in the View scale the view but beyond a certain point. Since we are setting a max height, initially the composable function will be loaded with the height required by the content, and is allowed to scale up to the set max height. In Compose, we use the <code class="language-plaintext highlighter-rouge">Modifier.heightIn(max)</code> to set the max height for a component.</p>

<h3 id="pro-2">Pro</h3>
<ul>
  <li>Easy to implement with minimal code changes.</li>
</ul>

<h3 id="con-2">Con</h3>
<ul>
  <li>Requires hardcoding a maximum height, which may be challenging for dynamic layouts.</li>
</ul>

<p>Example</p>
<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nd">@Preview</span>
<span class="nd">@Composable</span>
<span class="k">private</span> <span class="k">fun</span> <span class="nf">PreviewNestedWithWeight</span><span class="p">()</span> <span class="p">{</span>
    <span class="nc">LazyColumn</span> <span class="p">{</span>
        <span class="nf">items</span><span class="p">(</span><span class="mi">2</span><span class="p">)</span> <span class="p">{</span> <span class="n">num</span> <span class="p">-&gt;</span>
            <span class="k">if</span> <span class="p">(</span><span class="n">num</span> <span class="p">==</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span>
                <span class="c1">// Using a fixed height for the LazyColumn as I know the height of each item</span>
                <span class="c1">// and the number of items in the list. ie: 100.dp * 10 = 1000.dp</span>
                <span class="nc">LazyColumn</span><span class="p">(</span><span class="n">modifier</span> <span class="p">=</span> <span class="nc">Modifier</span><span class="p">.</span><span class="nf">height</span><span class="p">(</span><span class="mi">1000</span><span class="p">.</span><span class="n">dp</span><span class="p">))</span> <span class="p">{</span>
                    <span class="nf">items</span><span class="p">(</span><span class="mi">10</span><span class="p">)</span> <span class="p">{</span> <span class="n">i</span> <span class="p">-&gt;</span>
                        <span class="nc">Text</span><span class="p">(</span>
                            <span class="n">text</span> <span class="p">=</span> <span class="n">i</span><span class="p">.</span><span class="nf">toString</span><span class="p">(),</span>
                            <span class="nc">Modifier</span>
                                <span class="p">.</span><span class="nf">size</span><span class="p">(</span><span class="n">width</span> <span class="p">=</span> <span class="mi">100</span><span class="p">.</span><span class="n">dp</span><span class="p">,</span> <span class="n">height</span> <span class="p">=</span> <span class="mi">100</span><span class="p">.</span><span class="n">dp</span><span class="p">)</span>
                                <span class="p">.</span><span class="nf">background</span><span class="p">(</span><span class="nc">Color</span><span class="p">.</span><span class="nc">Gray</span><span class="p">)</span>
                        <span class="p">)</span>
                    <span class="p">}</span>
                <span class="p">}</span>
            <span class="p">}</span> <span class="k">else</span> <span class="p">{</span>
                <span class="c1">// Using an upper bound for the height of the LazyColumn. This can be some</span>
                <span class="c1">// arbitrary value like 10000.dp which we don't expect this Column to reach.</span>
                <span class="nc">LazyColumn</span><span class="p">(</span><span class="n">modifier</span> <span class="p">=</span> <span class="nc">Modifier</span><span class="p">.</span><span class="nf">heightIn</span><span class="p">(</span><span class="n">max</span> <span class="p">=</span> <span class="mi">10000</span><span class="p">.</span><span class="n">dp</span><span class="p">))</span> <span class="p">{</span>
                    <span class="nf">items</span><span class="p">(</span><span class="mi">10</span><span class="p">)</span> <span class="p">{</span> <span class="n">i</span> <span class="p">-&gt;</span>
                        <span class="nc">Text</span><span class="p">(</span>
                            <span class="n">text</span> <span class="p">=</span> <span class="n">i</span><span class="p">.</span><span class="nf">toString</span><span class="p">(),</span>
                            <span class="nc">Modifier</span>
                                <span class="p">.</span><span class="nf">size</span><span class="p">(</span><span class="mi">100</span><span class="p">.</span><span class="n">dp</span><span class="p">)</span>
                                <span class="p">.</span><span class="nf">background</span><span class="p">(</span><span class="nc">Color</span><span class="p">.</span><span class="nc">DarkGray</span><span class="p">)</span>
                        <span class="p">)</span>
                    <span class="p">}</span>
                <span class="p">}</span>
            <span class="p">}</span>
        <span class="p">}</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<h4 id="conclusion">Conclusion</h4>
<p>We explored several approaches to address the crash caused by nested LazyColumns or LazyRows in Compose. Personally, I prefer setting a max height using <code class="language-plaintext highlighter-rouge">Modifier.heightIn(max)</code> as it is straightforward and requires minimal code changes. However, the best solution depends on your specific requirements. I hope these solutions help you resolve the nested scrolling issue in your Compose application.</p>]]></content><author><name>Saran</name></author><category term="Compose" /><category term="Android" /><category term="scrolling" /><category term="UI" /><category term="Android" /><category term="Compose" /><summary type="html"><![CDATA[Implementing nested lists is a common requirement in many applications, which we have traditionally managed using RecyclerView. However, in Jetpack Compose, attempting nested LazyColumn or LazyRow can lead to the following crash. Exception: java.lang.IllegalStateException: Vertically scrollable component was measured with an infinity maximum height constraints, which is disallowed. One of the common reasons is nesting layouts like LazyColumn and Column(Modifier.verticalScroll()). If you want to add a header before the list of items please add a header as a separate item() before the main items() inside the LazyColumn scope. There are could be other reasons for this to happen: your ComposeView was added into a LinearLayout with some weight, you applied Modifier.wrapContentSize(unbounded = true) or wrote a custom layout. Please try to remove the source of infinite constraints in the hierarchy above the scrolling container. Now let’s try to understand the issue here. LazyColumns by default have an infinite maximum height because they lazy-load items. Due of this nature, it cannot determine its height and thus uses an infinite as its height. Also, since LazyColumns are scrollable, it needs to keep track of the items visible on the screen. When an item is scrolled out of the screen, a new item gets added. Now since the internal LazyColum’s height is infinity, it disrupts the outer LazyColumn from knowing its child’s actual height. This is why we are not allowed to nest LazyColumns. Now that we understand the problem, let’s look what solutions are avilable to us. 1. Flatten the list One way to solve the nesting of LazyColumns is to flatten the list, such that we can get rid of the internal LazyColumn. This way we will have only 1 lazy column which solves the problem. Pro Solves the LazyColumn issue without adding any new components. Con Loses data hierarchy. EG: If we are building a feed like Facebook, where we have a post and 2 comments on the post and then the next post. If the user likes a comment, then we can’t immediately identify which post the comment belongs to because our list is flattened. 2. Compute the height of the nested LazyColumn As we found earlier, the infinite height of the LazyColumn is the root cause of the issue. This is understandable as there would be different-sized elements loaded into the LazyColumn. However, this is not the case always. For example, we are building a contacts app or a simple calendar events list. Here the height of the component redered by the list remains consistent. In such cases, we can compute the height of our list in dp and set it as the height of our inner LazyColumn. This caused, the height of the list nit be infinite and which solves the problem. EG: The height of 1 item in the nested list is of 40.dp and the list has 10 items. It means we can set the height of the LazyColumn to 40 * 10 = 400.dp Pro Unlike a flattened list, the hierarchy is still maintained. Con Computing the expected height can be challenging depending on the data rendered by the composable functions. 3. Setting max height If you have worked with Veiws before there is an attribute android:maxWidth &amp; android:maxHeight. The purpose of this is to set the content in the View scale the view but beyond a certain point. Since we are setting a max height, initially the composable function will be loaded with the height required by the content, and is allowed to scale up to the set max height. In Compose, we use the Modifier.heightIn(max) to set the max height for a component. Pro Easy to implement with minimal code changes. Con Requires hardcoding a maximum height, which may be challenging for dynamic layouts. Example @Preview @Composable private fun PreviewNestedWithWeight() { LazyColumn { items(2) { num -&gt; if (num == 0) { // Using a fixed height for the LazyColumn as I know the height of each item // and the number of items in the list. ie: 100.dp * 10 = 1000.dp LazyColumn(modifier = Modifier.height(1000.dp)) { items(10) { i -&gt; Text( text = i.toString(), Modifier .size(width = 100.dp, height = 100.dp) .background(Color.Gray) ) } } } else { // Using an upper bound for the height of the LazyColumn. This can be some // arbitrary value like 10000.dp which we don't expect this Column to reach. LazyColumn(modifier = Modifier.heightIn(max = 10000.dp)) { items(10) { i -&gt; Text( text = i.toString(), Modifier .size(100.dp) .background(Color.DarkGray) ) } } } } } } Conclusion We explored several approaches to address the crash caused by nested LazyColumns or LazyRows in Compose. Personally, I prefer setting a max height using Modifier.heightIn(max) as it is straightforward and requires minimal code changes. However, the best solution depends on your specific requirements. I hope these solutions help you resolve the nested scrolling issue in your Compose application.]]></summary></entry><entry><title type="html">How I’m saving my 7-10 hours of productivity with a simple trick</title><link href="https://saran.sankaran.dev/software%20engineering/How-Im-saving-my-7-10-hours-of-productivity-with-a-simple-trick/" rel="alternate" type="text/html" title="How I’m saving my 7-10 hours of productivity with a simple trick" /><published>2024-05-12T00:00:00+05:30</published><updated>2024-05-12T00:00:00+05:30</updated><id>https://saran.sankaran.dev/software%20engineering/How-Im-saving-my-7-10-hours-of-productivity-with-a-simple-trick</id><content type="html" xml:base="https://saran.sankaran.dev/software%20engineering/How-Im-saving-my-7-10-hours-of-productivity-with-a-simple-trick/"><![CDATA[<p>In my role as a software engineer, it’s crucial to maintain high levels of productivity. While some loss of productivity is due to ineffective habits like checking at our phone very often, some loss in productivity also happens due to ineffective use of technologies available to us. When working on Android a lot of my productivity is lost due to the extremely long &amp; high memory-consuming Android builds. This is usually not a problem when I’m working on a feature where I have already run the build a few times, as most of the build output would be cached and only new changes get compiled.</p>

<p>When a QA engineer raises a bug with small inconsistencies, such as missing alignment or a crash due to an <a href="https://en.wikipedia.org/wiki/Off-by-one_error">off-by-1 error</a>, it means I have to stop what I’m doing and address the reported issue. I dislike nothing more than having to switch branches, pull the master, fix the minor bug, run the build, and wait for the entire build to verify the fix. This becomes more frustrating when there’s no build-cache because we are working on a new branch. Once the issue is fixed, I have to switch back to the previous branch, run the build again, and wait for the entire build to complete, all because this is a new branch.</p>

<p>When working in a team, we often learn something new from each other. Similarly, when working with a senior engineer, I learned a solution to this problem, which is to keep multiple copies of the repository.</p>

<p>Having multiple copies of the repository saves me from waiting for two fresh builds, which can cause 20-30 minutes of lost productivity. With multiple copies of the repository, I can verify the fix for the issue on my primary project along with the changes I was working on for a new feature. Once verified, I apply the same code in the secondary repository and publish it to raise the pull request.</p>

<p>I even go 1 step ahead and never open the secondary project in my IDE. Instead, I copy the file with the fix from the primary repository into the secondary repository. Of course, this only works for simple fixes.</p>

<p>I wish I had known this hack earlier in my career I would have saved hundreds of hours wasted switching the branch and triggering fresh builds.</p>]]></content><author><name>Saran</name></author><category term="Software engineering" /><category term="git" /><category term="project" /><category term="build" /><summary type="html"><![CDATA[In my role as a software engineer, it’s crucial to maintain high levels of productivity. While some loss of productivity is due to ineffective habits like checking at our phone very often, some loss in productivity also happens due to ineffective use of technologies available to us. When working on Android a lot of my productivity is lost due to the extremely long &amp; high memory-consuming Android builds. This is usually not a problem when I’m working on a feature where I have already run the build a few times, as most of the build output would be cached and only new changes get compiled. When a QA engineer raises a bug with small inconsistencies, such as missing alignment or a crash due to an off-by-1 error, it means I have to stop what I’m doing and address the reported issue. I dislike nothing more than having to switch branches, pull the master, fix the minor bug, run the build, and wait for the entire build to verify the fix. This becomes more frustrating when there’s no build-cache because we are working on a new branch. Once the issue is fixed, I have to switch back to the previous branch, run the build again, and wait for the entire build to complete, all because this is a new branch. When working in a team, we often learn something new from each other. Similarly, when working with a senior engineer, I learned a solution to this problem, which is to keep multiple copies of the repository. Having multiple copies of the repository saves me from waiting for two fresh builds, which can cause 20-30 minutes of lost productivity. With multiple copies of the repository, I can verify the fix for the issue on my primary project along with the changes I was working on for a new feature. Once verified, I apply the same code in the secondary repository and publish it to raise the pull request. I even go 1 step ahead and never open the secondary project in my IDE. Instead, I copy the file with the fix from the primary repository into the secondary repository. Of course, this only works for simple fixes. I wish I had known this hack earlier in my career I would have saved hundreds of hours wasted switching the branch and triggering fresh builds.]]></summary></entry><entry><title type="html">Backing property (Direct assignment vs Getters) in Kotlin</title><link href="https://saran.sankaran.dev/kotlin/Backing-property-Direct-assignment-vs-Getters-in-Kotlin/" rel="alternate" type="text/html" title="Backing property (Direct assignment vs Getters) in Kotlin" /><published>2020-09-01T00:00:00+05:30</published><updated>2020-09-01T00:00:00+05:30</updated><id>https://saran.sankaran.dev/kotlin/Backing-property-Direct-assignment-vs-Getters-in-Kotlin</id><content type="html" xml:base="https://saran.sankaran.dev/kotlin/Backing-property-Direct-assignment-vs-Getters-in-Kotlin/"><![CDATA[<p>When working with Android &amp; MVVM, we use <code class="language-plaintext highlighter-rouge">LiveData</code> to propagate any changes to the View. To do it we use a backing property. What we intend to achieve by doing it is to hide the mutability of <code class="language-plaintext highlighter-rouge">LiveData</code> from external classes like shown below.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">ViewModel</span> <span class="p">{</span>
  <span class="k">private</span> <span class="kd">val</span> <span class="py">_mLiveData</span> <span class="p">=</span> <span class="nc">MutableLiveData</span><span class="p">&lt;</span><span class="nc">Boolean</span><span class="p">&gt;()</span>
  <span class="kd">val</span> <span class="py">mLiveData</span><span class="p">:</span> <span class="nc">LiveData</span><span class="p">&lt;</span><span class="nc">Boolean</span><span class="p">&gt;</span> <span class="p">=</span> <span class="n">_mLiveData</span>
<span class="p">}</span>
</code></pre></div></div>
<p>OR</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">ViewModel</span> <span class="p">{</span>
  <span class="k">private</span> <span class="kd">val</span> <span class="py">_mLiveData</span> <span class="p">=</span> <span class="nc">MutableLiveData</span><span class="p">&lt;</span><span class="nc">Boolean</span><span class="p">&gt;()</span>
  <span class="kd">val</span> <span class="py">mLiveData</span><span class="p">:</span> <span class="nc">LiveData</span><span class="p">&lt;</span><span class="nc">Boolean</span><span class="p">&gt;</span>
    <span class="k">get</span><span class="p">()</span> <span class="p">=</span> <span class="n">_mLiveData</span>
<span class="p">}</span>
</code></pre></div></div>

<p>When we look at it, both methods look similar. However, that’s not the case. Let’s look at some examples.</p>

<h5 id="1-with-direct-assignment">1. With Direct assignment</h5>
<p>We will start with the first code snippet, but with little bit logging.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">Test</span><span class="p">()</span> <span class="p">{</span>
  <span class="k">private</span> <span class="kd">val</span> <span class="py">a</span> <span class="p">=</span> <span class="nf">mutableListOf</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="mi">10</span><span class="p">,</span> <span class="mi">15</span><span class="p">)</span>
  <span class="kd">val</span> <span class="py">b</span> <span class="p">:</span> <span class="nc">List</span><span class="p">&lt;</span><span class="nc">Int</span><span class="p">&gt;</span> <span class="p">=</span> <span class="n">a</span> <span class="c1">// Hiding the mutablity from a external class</span>
  
  <span class="k">fun</span> <span class="nf">updateList</span><span class="p">()</span> <span class="p">{</span>
    <span class="n">a</span><span class="p">.</span><span class="nf">clear</span><span class="p">()</span>
    <span class="n">a</span><span class="p">.</span><span class="nf">apply</span> <span class="p">{</span>
      <span class="nf">add</span><span class="p">(</span><span class="mi">2</span><span class="p">)</span>
      <span class="nf">add</span><span class="p">(</span><span class="mi">4</span><span class="p">)</span>
      <span class="nf">add</span><span class="p">(</span><span class="mi">6</span><span class="p">)</span>
    <span class="p">}</span>
  <span class="p">}</span>
<span class="p">}</span>

<span class="kd">val</span> <span class="py">t</span> <span class="p">=</span> <span class="nc">Test</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
<span class="n">t</span><span class="p">.</span><span class="nf">updateList</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"updated list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
</code></pre></div></div>

<p>And the output when the above code gets executed is.</p>
<pre><code class="language-txt">list = 5, 10, 15
updated list = 2, 4, 6
</code></pre>

<p>Well, what’s wrong? It worked, didn’t it?</p>

<p>The answer is Yes, it worked. Now let’s make some changes to the above code.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">Test</span><span class="p">()</span> <span class="p">{</span>
  <span class="k">private</span> <span class="kd">var</span> <span class="py">a</span> <span class="p">=</span> <span class="nf">mutableListOf</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="mi">10</span><span class="p">,</span> <span class="mi">15</span><span class="p">)</span>
  <span class="kd">val</span> <span class="py">b</span> <span class="p">:</span> <span class="nc">List</span><span class="p">&lt;</span><span class="nc">Int</span><span class="p">&gt;</span> <span class="p">=</span> <span class="n">a</span>  <span class="c1">// Hiding the mutablity from a external class</span>
  
  <span class="k">fun</span> <span class="nf">updateList</span><span class="p">()</span> <span class="p">{</span>
    <span class="n">a</span> <span class="p">=</span> <span class="nf">mutableListOf</span><span class="p">(</span><span class="mi">2</span><span class="p">,</span> <span class="mi">4</span><span class="p">,</span> <span class="mi">6</span><span class="p">)</span>
  <span class="p">}</span>
<span class="p">}</span>

<span class="kd">val</span> <span class="py">t</span> <span class="p">=</span> <span class="nc">Test</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
<span class="n">t</span><span class="p">.</span><span class="nf">updateList</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"updated list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
</code></pre></div></div>

<p>And the output of the above code is</p>
<pre><code class="language-txt">list = 5, 10, 15
updated list = 5, 10, 15
</code></pre>

<p>Wait, what? How did the output change?
Let’s first understand what changed.</p>
<ol>
  <li><code class="language-plaintext highlighter-rouge">a</code> become mutable (a was <code class="language-plaintext highlighter-rouge">val</code> but is <code class="language-plaintext highlighter-rouge">var</code> now)</li>
  <li>Implementation of <code class="language-plaintext highlighter-rouge">updateList()</code> changed from updating the current list to creating a new list with new values.</li>
</ol>

<p>Now let’s try to understand why did it print <code class="language-plaintext highlighter-rouge">updated list = 5, 10, 15</code> instead of <code class="language-plaintext highlighter-rouge">updated list = 2, 4, 6</code>. For that, let’s look under the hood and understand how does this kotlin code look when converted to Java using byte code converter.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// Only has code relevent to us</span>
<span class="kd">class</span> <span class="nc">Test</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="nc">List</span> <span class="n">a</span><span class="o">;</span>
  <span class="kd">private</span> <span class="kd">final</span> <span class="nc">List</span> <span class="n">b</span><span class="o">;</span>

  <span class="kd">public</span> <span class="nf">Test</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">this</span><span class="o">.</span><span class="na">b</span> <span class="o">=</span> <span class="k">this</span><span class="o">.</span><span class="na">a</span><span class="o">;</span>
  <span class="o">}</span>

  <span class="kd">public</span> <span class="kt">void</span> <span class="nf">updateList</span><span class="o">()</span> <span class="o">{</span>
    <span class="n">a</span> <span class="o">=</span> <span class="nc">CollectionsKt</span><span class="o">.</span><span class="na">mutableListOf</span><span class="o">(</span><span class="k">new</span> <span class="nc">Integer</span><span class="o">[]{</span><span class="mi">2</span><span class="o">,</span> <span class="mi">4</span><span class="o">,</span> <span class="mi">6</span><span class="o">});</span>
  <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>
<p>As we can see here, <code class="language-plaintext highlighter-rouge">b</code> is like an indirect reference to the memory pointing to exact same address pointed by <code class="language-plaintext highlighter-rouge">a</code>. Now if we look at the <code class="language-plaintext highlighter-rouge">updateList()</code> above, what we did was change the address pointed by <code class="language-plaintext highlighter-rouge">a</code> by assigning a new value. However, we never update <code class="language-plaintext highlighter-rouge">b</code> to point to same address. So the <code class="language-plaintext highlighter-rouge">b</code> is still pointing to the old address where <code class="language-plaintext highlighter-rouge">a</code> was pointing. Which produced the bug in our code.</p>

<h5 id="2-with-a-property-getter">2. With a property getter</h5>

<p>Let’s take the above code, which was buggy and use a getter instead of assignment.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">Test</span><span class="p">()</span> <span class="p">{</span>
  <span class="k">private</span> <span class="kd">var</span> <span class="py">a</span> <span class="p">=</span> <span class="nf">mutableListOf</span><span class="p">(</span><span class="mi">5</span><span class="p">,</span> <span class="mi">10</span><span class="p">,</span> <span class="mi">15</span><span class="p">)</span>
  <span class="kd">val</span> <span class="py">b</span> <span class="p">:</span> <span class="nc">List</span><span class="p">&lt;</span><span class="nc">Int</span><span class="p">&gt;</span>  <span class="c1">// Hiding the mutablity from a external class</span>
    <span class="k">get</span><span class="p">()</span> <span class="p">=</span> <span class="n">a</span>

  <span class="k">fun</span> <span class="nf">updateList</span><span class="p">()</span> <span class="p">{</span>
    <span class="n">a</span> <span class="p">=</span> <span class="nf">mutableListOf</span><span class="p">(</span><span class="mi">2</span><span class="p">,</span> <span class="mi">4</span><span class="p">,</span> <span class="mi">6</span><span class="p">)</span>
  <span class="p">}</span>
<span class="p">}</span>

<span class="kd">val</span> <span class="py">t</span> <span class="p">=</span> <span class="nc">Test</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
<span class="n">t</span><span class="p">.</span><span class="nf">updateList</span><span class="p">()</span>
<span class="nf">print</span><span class="p">(</span><span class="s">"updated list = "</span> <span class="p">+</span> <span class="n">t</span><span class="p">.</span><span class="n">b</span><span class="p">.</span><span class="nf">joinToString</span><span class="p">())</span>
</code></pre></div></div>

<p>And the output is</p>
<pre><code class="language-txt">list = 5, 10, 15
updated list = 2, 4, 6
</code></pre>

<p>Well, it worked as we expected. But why?</p>

<p>To understand why let’s look at the kotlin byte code decompiled to Java</p>
<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">class</span> <span class="nc">Test</span> <span class="o">{</span>
  <span class="kd">private</span> <span class="nc">List</span> <span class="n">a</span><span class="o">;</span>

  <span class="nd">@NotNull</span>
  <span class="kd">public</span> <span class="kd">final</span> <span class="nc">List</span> <span class="nf">getB</span><span class="o">()</span> <span class="o">{</span>
    <span class="k">return</span> <span class="k">this</span><span class="o">.</span><span class="na">a</span><span class="o">;</span>
  <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Well, here <code class="language-plaintext highlighter-rouge">b</code> is only acting as a getter of <code class="language-plaintext highlighter-rouge">a</code>. So whenever we call <code class="language-plaintext highlighter-rouge">b</code> it will always have the latest value of <code class="language-plaintext highlighter-rouge">a</code>. Isn’t this we always wanted?</p>

<h3 id="conclusion">Conclusion</h3>
<p>We often need to use the backing property. But, it’s always prone to bug and it’s difficult to spot them. Hence, always use the backing property via a getter.</p>]]></content><author><name>Saran</name></author><category term="Kotlin" /><category term="Android" /><category term="Kotlin" /><summary type="html"><![CDATA[When working with Android &amp; MVVM, we use LiveData to propagate any changes to the View. To do it we use a backing property. What we intend to achieve by doing it is to hide the mutability of LiveData from external classes like shown below. class ViewModel { private val _mLiveData = MutableLiveData&lt;Boolean&gt;() val mLiveData: LiveData&lt;Boolean&gt; = _mLiveData } OR class ViewModel { private val _mLiveData = MutableLiveData&lt;Boolean&gt;() val mLiveData: LiveData&lt;Boolean&gt; get() = _mLiveData } When we look at it, both methods look similar. However, that’s not the case. Let’s look at some examples. 1. With Direct assignment We will start with the first code snippet, but with little bit logging. class Test() { private val a = mutableListOf(5, 10, 15) val b : List&lt;Int&gt; = a // Hiding the mutablity from a external class fun updateList() { a.clear() a.apply { add(2) add(4) add(6) } } } val t = Test() print("list = " + t.b.joinToString()) t.updateList() print("updated list = " + t.b.joinToString()) And the output when the above code gets executed is. list = 5, 10, 15 updated list = 2, 4, 6 Well, what’s wrong? It worked, didn’t it? The answer is Yes, it worked. Now let’s make some changes to the above code. class Test() { private var a = mutableListOf(5, 10, 15) val b : List&lt;Int&gt; = a // Hiding the mutablity from a external class fun updateList() { a = mutableListOf(2, 4, 6) } } val t = Test() print("list = " + t.b.joinToString()) t.updateList() print("updated list = " + t.b.joinToString()) And the output of the above code is list = 5, 10, 15 updated list = 5, 10, 15 Wait, what? How did the output change? Let’s first understand what changed. a become mutable (a was val but is var now) Implementation of updateList() changed from updating the current list to creating a new list with new values. Now let’s try to understand why did it print updated list = 5, 10, 15 instead of updated list = 2, 4, 6. For that, let’s look under the hood and understand how does this kotlin code look when converted to Java using byte code converter. // Only has code relevent to us class Test { private List a; private final List b; public Test() { this.b = this.a; } public void updateList() { a = CollectionsKt.mutableListOf(new Integer[]{2, 4, 6}); } } As we can see here, b is like an indirect reference to the memory pointing to exact same address pointed by a. Now if we look at the updateList() above, what we did was change the address pointed by a by assigning a new value. However, we never update b to point to same address. So the b is still pointing to the old address where a was pointing. Which produced the bug in our code. 2. With a property getter Let’s take the above code, which was buggy and use a getter instead of assignment. class Test() { private var a = mutableListOf(5, 10, 15) val b : List&lt;Int&gt; // Hiding the mutablity from a external class get() = a fun updateList() { a = mutableListOf(2, 4, 6) } } val t = Test() print("list = " + t.b.joinToString()) t.updateList() print("updated list = " + t.b.joinToString()) And the output is list = 5, 10, 15 updated list = 2, 4, 6 Well, it worked as we expected. But why? To understand why let’s look at the kotlin byte code decompiled to Java class Test { private List a; @NotNull public final List getB() { return this.a; } } Well, here b is only acting as a getter of a. So whenever we call b it will always have the latest value of a. Isn’t this we always wanted? Conclusion We often need to use the backing property. But, it’s always prone to bug and it’s difficult to spot them. Hence, always use the backing property via a getter.]]></summary></entry><entry><title type="html">How to convert a callback based code into a Kotlin Coroutine</title><link href="https://saran.sankaran.dev/kotlin/How-to-convert-a-callback-code-into-kotlin-coroutine/" rel="alternate" type="text/html" title="How to convert a callback based code into a Kotlin Coroutine" /><published>2020-02-08T00:00:00+05:30</published><updated>2020-02-08T00:00:00+05:30</updated><id>https://saran.sankaran.dev/kotlin/How-to-convert-a-callback-code-into-kotlin-coroutine</id><content type="html" xml:base="https://saran.sankaran.dev/kotlin/How-to-convert-a-callback-code-into-kotlin-coroutine/"><![CDATA[<p>As you already know, Kotlin Co-routines turns a callback based code block into sequential code. Let me show you an example for the people who doesn’t know already.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">val</span> <span class="py">getUserCall</span> <span class="p">=</span> <span class="n">apiService</span><span class="p">.</span><span class="nf">getUser</span><span class="p">(</span><span class="mi">15</span><span class="p">)</span>
<span class="n">getUserCall</span><span class="p">.</span><span class="nf">enqueue</span><span class="p">(</span><span class="k">object</span><span class="p">:</span> <span class="nc">Callback</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;</span> <span class="p">{</span>
    <span class="k">override</span> <span class="k">fun</span> <span class="nf">onResponse</span><span class="p">(</span><span class="n">call</span><span class="p">:</span> <span class="nc">Call</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;,</span> <span class="n">response</span><span class="p">:</span> <span class="nc">Response</span><span class="p">&lt;</span><span class="err">user</span><span class="p">&gt;)</span> <span class="p">{</span>
        <span class="nf">doSomeThing</span><span class="p">(</span><span class="n">response</span><span class="p">.</span><span class="nf">body</span><span class="p">())</span>
    <span class="p">}</span>

    <span class="k">override</span> <span class="k">fun</span> <span class="nf">onFailure</span><span class="p">(</span><span class="n">call</span><span class="p">:</span> <span class="nc">Call</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;,</span> <span class="n">t</span><span class="p">:</span> <span class="nc">Throwable</span><span class="p">)</span> <span class="p">{</span>
        <span class="n">t</span><span class="p">.</span><span class="nf">printStackTrace</span><span class="p">()</span>
    <span class="p">}</span>
<span class="p">})</span>
</code></pre></div></div>

<p>This is how a typical callback based code would look like in Kotlin. But, aren’t we talking about co-routines, why do we still have callbacks?</p>

<p>Ok let me show you the above example using co-routines</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">launch</span> <span class="p">{</span>
    <span class="k">try</span> <span class="p">{</span>
        <span class="kd">val</span> <span class="py">user</span> <span class="p">=</span> <span class="n">apiService</span><span class="p">.</span><span class="nf">getUser</span><span class="p">(</span><span class="mi">15</span><span class="p">)</span>
        <span class="nf">doSomeThing</span><span class="p">(</span><span class="n">user</span><span class="p">)</span>
    <span class="p">}</span> <span class="k">catch</span><span class="p">(</span><span class="n">t</span><span class="p">:</span> <span class="nc">Throwable</span><span class="p">)</span> <span class="p">{</span>
        <span class="n">t</span><span class="p">.</span><span class="nf">printStackTrace</span><span class="p">()</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Cool!! but here we assume that <code class="language-plaintext highlighter-rouge">apiService.getUser(15)</code> is a function which supports co-rotines. However often that’s not the case, becasue usually we are using a framework or libraries, thats written on/or for Java. In such case, we can’t avoid using callbacks.</p>

<p>In such cases what we can do though is convert these callbacks into Kotlin co-routines. Lemme show you how!!</p>

<p>Let’s take the previous example of getting a user from a api call.</p>

<div class="language-kotlin highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">launch</span> <span class="p">{</span>
    <span class="k">try</span> <span class="p">{</span>
        <span class="kd">val</span> <span class="py">user</span> <span class="p">=</span> <span class="nf">getUser</span><span class="p">(</span><span class="n">apiService</span><span class="p">,</span> <span class="mi">15</span><span class="p">)</span>
        <span class="nf">doSomeThing</span><span class="p">(</span><span class="n">user</span><span class="p">)</span>
    <span class="p">}</span> <span class="k">catch</span><span class="p">(</span><span class="n">t</span><span class="p">:</span> <span class="nc">Throwable</span><span class="p">)</span> <span class="p">{</span>
        <span class="n">t</span><span class="p">.</span><span class="nf">printStackTrace</span><span class="p">()</span>
    <span class="p">}</span>
<span class="p">}</span>

<span class="k">suspend</span> <span class="k">fun</span> <span class="nf">getUser</span><span class="p">(</span><span class="n">apiService</span><span class="p">:</span> <span class="nc">Service</span><span class="p">,</span> <span class="n">id</span><span class="p">:</span> <span class="nc">Int</span><span class="p">)</span> <span class="p">=</span> <span class="n">suspendCoroutine</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;</span> <span class="p">{</span> <span class="n">continuation</span> <span class="p">-&gt;</span>
    <span class="kd">val</span> <span class="py">getUserCall</span> <span class="p">=</span> <span class="n">apiService</span><span class="p">.</span><span class="nf">getUser</span><span class="p">(</span><span class="mi">15</span><span class="p">)</span>
    <span class="n">getUserCall</span><span class="p">.</span><span class="nf">enqueue</span><span class="p">(</span><span class="k">object</span><span class="p">:</span> <span class="nc">Callback</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;</span> <span class="p">{</span>
		
        <span class="k">override</span> <span class="k">fun</span> <span class="nf">onResponse</span><span class="p">(</span><span class="n">call</span><span class="p">:</span> <span class="nc">Call</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;,</span> <span class="n">response</span><span class="p">:</span> <span class="nc">Response</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;)</span> <span class="p">{</span>
            <span class="n">continuation</span><span class="p">.</span><span class="nf">resume</span><span class="p">(</span><span class="n">response</span><span class="p">.</span><span class="nf">body</span><span class="p">())</span>
        <span class="p">}</span>

        <span class="k">override</span> <span class="k">fun</span> <span class="nf">onFailure</span><span class="p">(</span><span class="n">call</span><span class="p">:</span> <span class="nc">Call</span><span class="p">&lt;</span><span class="nc">User</span><span class="p">&gt;,</span> <span class="n">t</span><span class="p">:</span> <span class="nc">Throwable</span><span class="p">)</span> <span class="p">{</span>
            <span class="n">continuation</span><span class="p">.</span><span class="nf">resumeWithException</span><span class="p">(</span><span class="n">t</span><span class="p">)</span>
        <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Here we ar using a <code class="language-plaintext highlighter-rouge">suspendCoroutine {}</code> to convert a callback into a co-routine. In <code class="language-plaintext highlighter-rouge">getUser()</code> first we launch a <code class="language-plaintext highlighter-rouge">suspendCoroutine</code> block.</p>

<p class="notice--info"><strong>INFO:</strong> In order to use <code class="language-plaintext highlighter-rouge">suspendCoroutine{}</code> we declare <code class="language-plaintext highlighter-rouge">getUser()</code> as a <code class="language-plaintext highlighter-rouge">suspend</code> function.</p>

<p>It supplies a <code class="language-plaintext highlighter-rouge">continuation</code> as an parameter. We will be using this <code class="language-plaintext highlighter-rouge">continuation</code> to inform the coroutine to continue from the point where the function was suspended. We can also pass a result to the <code class="language-plaintext highlighter-rouge">continutaion</code> which will be returned when the suspended function returnes.</p>]]></content><author><name>Saran</name></author><category term="Kotlin" /><category term="Android" /><category term="Android-Studio" /><category term="Kotlin" /><category term="Co-routines" /><category term="Callback" /><category term="Java" /><summary type="html"><![CDATA[As you already know, Kotlin Co-routines turns a callback based code block into sequential code. Let me show you an example for the people who doesn’t know already. val getUserCall = apiService.getUser(15) getUserCall.enqueue(object: Callback&lt;User&gt; { override fun onResponse(call: Call&lt;User&gt;, response: Response&lt;user&gt;) { doSomeThing(response.body()) } override fun onFailure(call: Call&lt;User&gt;, t: Throwable) { t.printStackTrace() } }) This is how a typical callback based code would look like in Kotlin. But, aren’t we talking about co-routines, why do we still have callbacks? Ok let me show you the above example using co-routines launch { try { val user = apiService.getUser(15) doSomeThing(user) } catch(t: Throwable) { t.printStackTrace() } } Cool!! but here we assume that apiService.getUser(15) is a function which supports co-rotines. However often that’s not the case, becasue usually we are using a framework or libraries, thats written on/or for Java. In such case, we can’t avoid using callbacks. In such cases what we can do though is convert these callbacks into Kotlin co-routines. Lemme show you how!! Let’s take the previous example of getting a user from a api call. launch { try { val user = getUser(apiService, 15) doSomeThing(user) } catch(t: Throwable) { t.printStackTrace() } } suspend fun getUser(apiService: Service, id: Int) = suspendCoroutine&lt;User&gt; { continuation -&gt; val getUserCall = apiService.getUser(15) getUserCall.enqueue(object: Callback&lt;User&gt; { override fun onResponse(call: Call&lt;User&gt;, response: Response&lt;User&gt;) { continuation.resume(response.body()) } override fun onFailure(call: Call&lt;User&gt;, t: Throwable) { continuation.resumeWithException(t) } } Here we ar using a suspendCoroutine {} to convert a callback into a co-routine. In getUser() first we launch a suspendCoroutine block. INFO: In order to use suspendCoroutine{} we declare getUser() as a suspend function. It supplies a continuation as an parameter. We will be using this continuation to inform the coroutine to continue from the point where the function was suspended. We can also pass a result to the continutaion which will be returned when the suspended function returnes.]]></summary></entry><entry><title type="html">Publish your Android library in 6 easy to follow steps</title><link href="https://saran.sankaran.dev/android/publish-your-android-library-in-6-easy-to-follow-steps/" rel="alternate" type="text/html" title="Publish your Android library in 6 easy to follow steps" /><published>2019-09-10T00:00:00+05:30</published><updated>2019-09-10T00:00:00+05:30</updated><id>https://saran.sankaran.dev/android/publish-your-android-library-in-6-easy-to-follow-steps</id><content type="html" xml:base="https://saran.sankaran.dev/android/publish-your-android-library-in-6-easy-to-follow-steps/"><![CDATA[<p>This is a continuation of my <a href="https://saran.sankaran.dev/android/Have-you-ever-thought-what-are-libraries-in-Android-and-how-to-build-them/">last blog</a> which was about building an Android library. In it, we learned when and why do we need to build a library. In this post, we will understand how do we distribute this cool library we just built and how do we make our library available for other developers to use.</p>

<h3 id="how-the-distribution-of-library-work-on-android">How the distribution of library work on Android</h3>

<p>In Android, <a href="https://gradle.org/">Gradle</a> is our default build system. In Gradle to include a library, we add the name of a library in the <code class="language-plaintext highlighter-rouge">build.gradle</code> file. But, how does it find the library just by including a single line in the build file? The answer is it looks up for the library in some cloud repository and downloads it. One such famous cloud repository is <a href="https://jcenter.bintray.com/">Jcenter</a> and is by default included when we create a new Android Project.</p>

<p>I will be continuing on my project from my last post. We will be publishing our library to JCenter through JFrog Bintray. It provides distribution of open-source libraries for free :)</p>

<h3 id="i-creating-an-account-and-setting-up-our-repository-on-bintray">I. Creating an Account and setting up our Repository on Bintray</h3>

<ol>
  <li>On <a href="https://bintray.com">Bintray</a> scroll to the bottom of the page and click on “For Open Source Plan Sign Up Here”</li>
  <li>Create an account</li>
  <li>Click on “Add new Repository” and it will present a page with a form.</li>
  <li>Enter the name for your Repository. It is like a project name.</li>
  <li>Since our library will be used through Gradle which is a Maven-based build system. You need to select  “Maven” in the “Type” dropdown.</li>
  <li>Select the Licence under which you want your library to be distributed. (To know which licence to choose, visit <a href="https://choosealicense.com">choosealicense.com</a>)</li>
  <li>Click on “Create” and you will be taken to the repository page.</li>
</ol>

<figure class="align-center">
  <img src="/assets/images/Screenshot_2019-08-25_1.png" alt="Creating a Repository on Bintray" style="width:62%;height:100%;" />
  <figcaption>Creating a Repository on Bintray</figcaption>
</figure>

<p class="notice--info"><strong>INFO:</strong> I have only named the mandatory fields.</p>

<h3 id="ii-adding-a-package-to-the-newly-created-repository">II. Adding a package to the newly created Repository</h3>

<ol>
  <li>Click on “Add new Package”</li>
  <li>
    <p>Enter a name for the package.</p>

    <p class="notice--danger"><strong>WARNING:</strong> This name will be used while including your library into a project by other developers.</p>

    <p class="notice--info"><strong>INFO:</strong> A common convention that developers follow is including their GitHub username in the package name.<br />
 <em>i.e: <code class="language-plaintext highlighter-rouge">com.github.saran2020.mylibrary</code></em></p>
  </li>
  <li>You can choose the same licence which you choose while creating your repository.</li>
  <li>Enter your GitHub project URL into the “Version Control” field.</li>
</ol>

<figure class="align-center">
  <img src="/assets/images/Screenshot_2019-08-25.png" alt="Creating new package" style="width:62%;height:100%;" />
  <figcaption>Creating new package</figcaption>
</figure>

<h3 id="iii-saving-the-bintray-api-key">III. Saving the bintray API key.</h3>
<p>Open “Edit Profile” and go to “API Key” section and save the API key somewhere. We will need this API Key when we automate the release of a new version.</p>

<figure class="align-center">
  <img src="/assets/images/Screenshot_2019-08-27_2.png" alt="Copy API key" style="width:62%;height:100%;" />
  <figcaption>Copy API key</figcaption>
</figure>

<hr />
<p>We have almost completed setting up our library on Bintray. We will now be moving ahead to automating our release from Android Studio. I have shared a <a href="https://github.com/saran2020/RootProject">sample project</a> on Github You can go through the <a href="https://github.com/saran2020/RootProject/commits/master">commits</a> while following my steps here.</p>

<p>Before continuing to the next section, we need to clear some terms I have used in the below steps.</p>

<dl>
  <dt>RootProject</dt>
  <dd>is the name of my project. Therefore, RootProject’s build.gradle will mean your projects build.gradle file.</dd>
  <dt>app</dt>
  <dd>is the name of my app module. So, “app” module build.gradle will mean your app module’s build.gradle file.</dd>
  <dt>library</dt>
  <dd>is the name of my library module. Hence, “library” module build.gradle will mean your library build.gradle file.</dd>
</dl>

<h3 id="iv-automating-release-of-our-library">IV. Automating release of our library.</h3>
<ol>
  <li>Add Bintray Gradle plugin and maven Gradle plugin to the RootProject <code class="language-plaintext highlighter-rouge">build.gradle</code> (Commit)
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">buildscript</span> <span class="o">{</span>
 <span class="o">...</span>
 <span class="n">dependencies</span> <span class="o">{</span>
     <span class="o">...</span>
     <span class="n">classpath</span> <span class="s2">"com.jfrog.bintray.gradle:gradle-bintray-plugin:1.8.4"</span>
     <span class="n">classpath</span> <span class="s2">"com.github.dcendents:android-maven-gradle-plugin:2.1"</span>
 <span class="o">}</span>
<span class="o">}</span>
</code></pre></div>    </div>
  </li>
  <li>Add version details to gradle.properties file.
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">versionName</span><span class="o">=</span><span class="mf">0.1</span>
 <span class="n">versionCode</span><span class="o">=</span><span class="mi">1</span> 
</code></pre></div>    </div>
    <p>We will be referring to these version code when sending out a new release. Making it easier for you to release a new version, without making changes to the <code class="language-plaintext highlighter-rouge">build.gradle</code> file.</p>
  </li>
  <li>Add Bintray authentication details to <code class="language-plaintext highlighter-rouge">local.properties</code> file.
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">bintray</span><span class="o">.</span><span class="na">user</span><span class="o">=&lt;</span><span class="n">bintray_username</span><span class="o">&gt;</span>
 <span class="n">bintray</span><span class="o">.</span><span class="na">gpg</span><span class="o">.</span><span class="na">password</span><span class="o">=&lt;</span><span class="n">bintray_password</span><span class="o">&gt;</span>
 <span class="n">bintray</span><span class="o">.</span><span class="na">apikey</span><span class="o">=&lt;</span><span class="n">bintray_apikey</span><span class="o">&gt;</span>
</code></pre></div>    </div>
    <p>You will be replacing the &lt;bintray_username&gt; with your Bintray username, &lt;bintray_password&gt; with your password and &lt;bintray_apikey&gt; with your “API key” from <em>step III</em> above.</p>

    <p class="notice--danger"><strong>WARNING:</strong> You need to make sure that <code class="language-plaintext highlighter-rouge">local.properties</code> file is included in the <code class="language-plaintext highlighter-rouge">.gitignore</code> file. Or else you might end up exposing your username password or API Key to GitHub accidentally.</p>
  </li>
  <li>Include upload script to the library <code class="language-plaintext highlighter-rouge">build.gradle</code> file.
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">repositories</span> <span class="o">{</span>
 	<span class="n">mavenCentral</span><span class="o">()</span>
 <span class="o">}</span>

 <span class="c1">// Add these lines to publish library to bintray. This is the readymade scripts made by github user nuuneoi to make uploading to bintray easy.</span>
 <span class="c1">// Place it at the end of the file</span>
 <span class="k">if</span> <span class="o">(</span><span class="n">project</span><span class="o">.</span><span class="na">rootProject</span><span class="o">.</span><span class="na">file</span><span class="o">(</span><span class="s1">'local.properties'</span><span class="o">).</span><span class="na">exists</span><span class="o">())</span> <span class="o">{</span>
 	<span class="n">apply</span> <span class="nl">from:</span> <span class="s1">'https://raw.githubusercontent.com/nuuneoi/JCenter/master/installv1.gradle'</span>
 	<span class="n">apply</span> <span class="nl">from:</span> <span class="s1">'https://raw.githubusercontent.com/nuuneoi/JCenter/master/bintrayv1.gradle'</span>
 <span class="o">}</span>
</code></pre></div>    </div>

    <p>This code will be added to the end of the library <code class="language-plaintext highlighter-rouge">build.gradle</code> file. This is some script created by other developers, which will help us automating our upload.</p>
  </li>
  <li>Configuring the library for upload.
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">apply</span> <span class="nl">plugin:</span><span class="o">...</span>

 <span class="n">ext</span> <span class="o">{</span>
 	<span class="n">bintrayRepo</span> <span class="o">=</span> <span class="s1">'MyLibrary'</span>
 	<span class="n">bintrayName</span> <span class="o">=</span> <span class="s1">'com.github.saran2020.mylibrary'</span>

 	<span class="n">libraryName</span> <span class="o">=</span> <span class="s1">'MyLibrary'</span>

 	<span class="n">publishedGroupId</span> <span class="o">=</span> <span class="s1">'com.github.saran2020.mylibrary'</span>
 	<span class="n">artifact</span> <span class="o">=</span> <span class="s1">'MyLibrary'</span>
 	<span class="n">libraryVersion</span> <span class="o">=</span> <span class="s1">'1.0'</span>

 	<span class="n">libraryDescription</span> <span class="o">=</span> <span class="s2">"Demo"</span>

 	<span class="n">siteUrl</span> <span class="o">=</span> <span class="s1">'https://github.com/saran2020/MyLibrary'</span>
 	<span class="n">gitUrl</span> <span class="o">=</span> <span class="s1">'https://github.com/saran2020/MyLibrary.git'</span>

 	<span class="n">developerId</span> <span class="o">=</span> <span class="s1">'saran2020'</span>
 	<span class="n">developerName</span> <span class="o">=</span> <span class="s1">'Saran Sankaran'</span>
 	<span class="n">developerEmail</span> <span class="o">=</span> <span class="s1">'sands.developer@gmail.com'</span>

 	<span class="n">licenseName</span> <span class="o">=</span> <span class="s1">'GNU GENERAL PUBLIC LICENSE'</span>
 	<span class="n">licenseUrl</span> <span class="o">=</span> <span class="s1">'https://www.gnu.org/licenses/gpl-3.0.en.html'</span>
 	<span class="n">allLicenses</span> <span class="o">=</span> <span class="o">[</span><span class="s2">"GPL-3.0"</span><span class="o">]</span>
 <span class="o">}</span>

 <span class="n">android</span> <span class="o">{</span>
     <span class="o">...</span>
 <span class="o">}</span>
</code></pre></div>    </div>

    <p>Add the above code to the library <code class="language-plaintext highlighter-rouge">build.gradle</code> after apply plugin and before android section.</p>
  </li>
  <li>Reading the version information from <code class="language-plaintext highlighter-rouge">gradle.properties</code> file, which we added in step 2
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="n">ext</span> <span class="o">{</span>
     <span class="o">...</span>
     <span class="n">libraryVersion</span> <span class="o">=</span> <span class="n">project</span><span class="o">.</span><span class="na">versionName</span>
     <span class="o">...</span>
 <span class="o">}</span>

 <span class="n">android</span><span class="o">{</span>
     <span class="n">defaultConfig</span> <span class="o">{</span>
         <span class="o">...</span>
         <span class="n">versionCode</span> <span class="n">project</span><span class="o">.</span><span class="na">versionCode</span><span class="o">.</span><span class="na">toInteger</span><span class="o">()</span>
         <span class="n">versionName</span> <span class="n">project</span><span class="o">.</span><span class="na">versionName</span>
         <span class="o">...</span>
     <span class="o">}</span>
 <span class="o">}</span>
</code></pre></div>    </div>

    <p>You need to <strong>replace</strong> the existing <code class="language-plaintext highlighter-rouge">libraryVersion</code> in the <code class="language-plaintext highlighter-rouge">ext</code> section and <code class="language-plaintext highlighter-rouge">versionCode</code> and <code class="language-plaintext highlighter-rouge">versionName</code> in the <code class="language-plaintext highlighter-rouge">defaultConfig</code> section with the above code.</p>

    <p>Whenever you want to release a new version, you just need to update the version in <code class="language-plaintext highlighter-rouge">gradle.properties</code>.</p>
  </li>
  <li>Disabling creation of JavaDocs.
    <div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code> <span class="o">...</span>
 <span class="n">subprojects</span> <span class="o">{</span>
 	<span class="n">tasks</span><span class="o">.</span><span class="na">withType</span><span class="o">(</span><span class="n">Javadoc</span><span class="o">).</span><span class="na">all</span> <span class="o">{</span> <span class="n">enabled</span> <span class="o">=</span> <span class="kc">false</span> <span class="o">}</span>
 <span class="o">}</span>
</code></pre></div>    </div>
    <p>Add the below code to the last line of RootProject <code class="language-plaintext highlighter-rouge">build.gradle</code> file. We are disabling the creation of Javadoc becasue, this some times give an error.</p>
  </li>
  <li>Uploading the project
    <div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="gp"> foo@bar:~$</span><span class="w"> </span>./gradlew assembleRelease bintrayUpload
</code></pre></div>    </div>
    <p>Run the above command by navigating to the root of your project through Terminal/CMD and wait till the upload finishes.</p>
  </li>
</ol>

<p>You can verify the upload by going to the <em>Repository -&gt; Package -&gt; Files -&gt; {Version you uploaded}</em> on Bintray dashboard and confirming that an .aar file exists.</p>

<figure class="align-center">
  <img src="/assets/images/Screenshot_2019-08-27.png" alt="Files after upload on Bintray" style="width:62%;height:100%;" />
  <figcaption>Files after upload on Bintray</figcaption>
</figure>

<h3 id="v-making-the-library-available-to-developers-through-jcenter">V. Making the library available to Developers through JCenter</h3>
<p>To make your library available to developers you will need to link your library package to Jcenter. You will find the option your package page. To add your library to Jcenter click on “Add to Jcenter”</p>

<figure class="align-center">
  <img src="/assets/images/Screenshot_2019-08-27_1.png" alt="Add to Jcenter" style="width:62%;height:100%;" />
  <figcaption>Add to Jcenter</figcaption>
</figure>

<p>It will open a page asking for comments. Tick the “is pom project” and add some comment about your project before submitting. It takes up to 24hrs to add your package to JCenter. Once it is added, an E-mail will be sent to you.</p>

<p class="notice--info"><strong>INFO:</strong> My package was accepted without any comment :)</p>

<h3 id="vi-releasing-a-new-version-of-your-library">VI. Releasing a new version of your library</h3>
<p>To release a new version, you need to update the version information in the <code class="language-plaintext highlighter-rouge">gradle.properties</code> file and run the command.</p>
<div class="language-console highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="gp">foo@bar:~$</span><span class="w"> </span>./gradlew assembleRelease bintrayUpload
</code></pre></div></div>
<hr />
<p>It is a good practice to check if your library has been published properly after every release. To do that, you need to comment out the</p>
<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">implementation</span> <span class="n">project</span><span class="o">&amp;</span><span class="n">lt</span><span class="o">;</span><span class="nl">path:</span> <span class="s1">'&lt;Your library name&gt;'</span><span class="o">&amp;</span><span class="n">gt</span><span class="o">;</span>
</code></pre></div></div>
<p>from the <code class="language-plaintext highlighter-rouge">dependencies</code> block and adding the version from the Jcenter which you just published directly like this</p>
<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">implementation</span> <span class="s1">'com.github.saran2020.mylibrary:MyLibrary:0.1'</span> 
</code></pre></div></div>

<p>It is also a good practice to mark every new release of your library on your GitHub repository.</p>

<hr />

<p>Follow me on <a href="https://x.com/SankaranDev">Twitter</a> for new updates or for any queries</p>]]></content><author><name>Saran</name></author><category term="Android" /><category term="Android" /><category term="Android-Studio" /><category term="Bintray11" /><category term="Jcenter" /><category term="Library" /><summary type="html"><![CDATA[This is a continuation of my last blog which was about building an Android library. In it, we learned when and why do we need to build a library. In this post, we will understand how do we distribute this cool library we just built and how do we make our library available for other developers to use. How the distribution of library work on Android In Android, Gradle is our default build system. In Gradle to include a library, we add the name of a library in the build.gradle file. But, how does it find the library just by including a single line in the build file? The answer is it looks up for the library in some cloud repository and downloads it. One such famous cloud repository is Jcenter and is by default included when we create a new Android Project. I will be continuing on my project from my last post. We will be publishing our library to JCenter through JFrog Bintray. It provides distribution of open-source libraries for free :) I. Creating an Account and setting up our Repository on Bintray On Bintray scroll to the bottom of the page and click on “For Open Source Plan Sign Up Here” Create an account Click on “Add new Repository” and it will present a page with a form. Enter the name for your Repository. It is like a project name. Since our library will be used through Gradle which is a Maven-based build system. You need to select “Maven” in the “Type” dropdown. Select the Licence under which you want your library to be distributed. (To know which licence to choose, visit choosealicense.com) Click on “Create” and you will be taken to the repository page. Creating a Repository on Bintray INFO: I have only named the mandatory fields. II. Adding a package to the newly created Repository Click on “Add new Package” Enter a name for the package. WARNING: This name will be used while including your library into a project by other developers. INFO: A common convention that developers follow is including their GitHub username in the package name. i.e: com.github.saran2020.mylibrary You can choose the same licence which you choose while creating your repository. Enter your GitHub project URL into the “Version Control” field. Creating new package III. Saving the bintray API key. Open “Edit Profile” and go to “API Key” section and save the API key somewhere. We will need this API Key when we automate the release of a new version. Copy API key We have almost completed setting up our library on Bintray. We will now be moving ahead to automating our release from Android Studio. I have shared a sample project on Github You can go through the commits while following my steps here. Before continuing to the next section, we need to clear some terms I have used in the below steps. RootProject is the name of my project. Therefore, RootProject’s build.gradle will mean your projects build.gradle file. app is the name of my app module. So, “app” module build.gradle will mean your app module’s build.gradle file. library is the name of my library module. Hence, “library” module build.gradle will mean your library build.gradle file. IV. Automating release of our library. Add Bintray Gradle plugin and maven Gradle plugin to the RootProject build.gradle (Commit) buildscript { ... dependencies { ... classpath "com.jfrog.bintray.gradle:gradle-bintray-plugin:1.8.4" classpath "com.github.dcendents:android-maven-gradle-plugin:2.1" } } Add version details to gradle.properties file. versionName=0.1 versionCode=1 We will be referring to these version code when sending out a new release. Making it easier for you to release a new version, without making changes to the build.gradle file. Add Bintray authentication details to local.properties file. bintray.user=&lt;bintray_username&gt; bintray.gpg.password=&lt;bintray_password&gt; bintray.apikey=&lt;bintray_apikey&gt; You will be replacing the &lt;bintray_username&gt; with your Bintray username, &lt;bintray_password&gt; with your password and &lt;bintray_apikey&gt; with your “API key” from step III above. WARNING: You need to make sure that local.properties file is included in the .gitignore file. Or else you might end up exposing your username password or API Key to GitHub accidentally. Include upload script to the library build.gradle file. repositories { mavenCentral() } // Add these lines to publish library to bintray. This is the readymade scripts made by github user nuuneoi to make uploading to bintray easy. // Place it at the end of the file if (project.rootProject.file('local.properties').exists()) { apply from: 'https://raw.githubusercontent.com/nuuneoi/JCenter/master/installv1.gradle' apply from: 'https://raw.githubusercontent.com/nuuneoi/JCenter/master/bintrayv1.gradle' } This code will be added to the end of the library build.gradle file. This is some script created by other developers, which will help us automating our upload. Configuring the library for upload. apply plugin:... ext { bintrayRepo = 'MyLibrary' bintrayName = 'com.github.saran2020.mylibrary' libraryName = 'MyLibrary' publishedGroupId = 'com.github.saran2020.mylibrary' artifact = 'MyLibrary' libraryVersion = '1.0' libraryDescription = "Demo" siteUrl = 'https://github.com/saran2020/MyLibrary' gitUrl = 'https://github.com/saran2020/MyLibrary.git' developerId = 'saran2020' developerName = 'Saran Sankaran' developerEmail = 'sands.developer@gmail.com' licenseName = 'GNU GENERAL PUBLIC LICENSE' licenseUrl = 'https://www.gnu.org/licenses/gpl-3.0.en.html' allLicenses = ["GPL-3.0"] } android { ... } Add the above code to the library build.gradle after apply plugin and before android section. Reading the version information from gradle.properties file, which we added in step 2 ext { ... libraryVersion = project.versionName ... } android{ defaultConfig { ... versionCode project.versionCode.toInteger() versionName project.versionName ... } } You need to replace the existing libraryVersion in the ext section and versionCode and versionName in the defaultConfig section with the above code. Whenever you want to release a new version, you just need to update the version in gradle.properties. Disabling creation of JavaDocs. ... subprojects { tasks.withType(Javadoc).all { enabled = false } } Add the below code to the last line of RootProject build.gradle file. We are disabling the creation of Javadoc becasue, this some times give an error. Uploading the project foo@bar:~$ ./gradlew assembleRelease bintrayUpload Run the above command by navigating to the root of your project through Terminal/CMD and wait till the upload finishes. You can verify the upload by going to the Repository -&gt; Package -&gt; Files -&gt; {Version you uploaded} on Bintray dashboard and confirming that an .aar file exists. Files after upload on Bintray V. Making the library available to Developers through JCenter To make your library available to developers you will need to link your library package to Jcenter. You will find the option your package page. To add your library to Jcenter click on “Add to Jcenter” Add to Jcenter It will open a page asking for comments. Tick the “is pom project” and add some comment about your project before submitting. It takes up to 24hrs to add your package to JCenter. Once it is added, an E-mail will be sent to you. INFO: My package was accepted without any comment :) VI. Releasing a new version of your library To release a new version, you need to update the version information in the gradle.properties file and run the command. foo@bar:~$ ./gradlew assembleRelease bintrayUpload It is a good practice to check if your library has been published properly after every release. To do that, you need to comment out the implementation project&amp;lt;path: '&lt;Your library name&gt;'&amp;gt; from the dependencies block and adding the version from the Jcenter which you just published directly like this implementation 'com.github.saran2020.mylibrary:MyLibrary:0.1' It is also a good practice to mark every new release of your library on your GitHub repository. Follow me on Twitter for new updates or for any queries]]></summary></entry><entry><title type="html">Have you ever thought what are libraries in Android and how to build them?</title><link href="https://saran.sankaran.dev/android/Have-you-ever-thought-what-are-libraries-in-Android-and-how-to-build-them/" rel="alternate" type="text/html" title="Have you ever thought what are libraries in Android and how to build them?" /><published>2019-07-05T00:00:00+05:30</published><updated>2019-07-05T00:00:00+05:30</updated><id>https://saran.sankaran.dev/android/Have-you-ever-thought-what-are-libraries-in-Android-and-how-to-build-them</id><content type="html" xml:base="https://saran.sankaran.dev/android/Have-you-ever-thought-what-are-libraries-in-Android-and-how-to-build-them/"><![CDATA[<p><img src="/assets/images/Screenshot-from-2019-07-15-12-38-56.png" alt="" /></p>

<p>When I started as an Android dev about 1.5 years back, I used to think, why do I need libraries when I can build all that cool stuff myself? However, as I completed about 2 months in the profession I started realizing the importance of the library and re-inventing the wheel every time was not at all a good idea. Every time I used a library from GitHub, I used to think, how do they build such cool library and how is it different from the normal app which I was used to building? If you wonder the same, you are in the right place. Today I will be explaining what libraries are, how you can build them, also why and how to distribute a library you built.</p>

<h3 id="what-is-a-library">What is a library?</h3>

<p>To know what is a library, you must know what a module is. Let’s learn what a module is.</p>

<p>A Module in a project follows the Separation of Concern (S) from the <a href="https://en.wikipedia.org/wiki/SOLID">SOLID principles</a> of Object-Oriented Design.<a href="https://stackoverflow.com/a/10967567/2758499">[*]</a> Modules help in splitting a project into smaller modules which would run independently or dependently on other modules.</p>

<p>Whenever we create a new project, Android Studio creates a single module which is an application module or app in short. App modules can run independently. Whereas, library modules cannot run independently. It is dependent on another application module which will invoke this library module for it to run. In Android, all of this is handled via build.gradle file of the application module.</p>

<h3 id="why-should-i-build-them">Why should I build them?</h3>

<p>When we work on multiple projects, we often write a lot of components in our project which we later need in other projects as well. What we end up doing is copy-pasting the code from project one to project two. Later we find that there was a bug in the component and we fix them in project two. However, the bug still exists in project one. Maintaining the same codebase twice is a challenging task and is not the best way to do it.</p>

<p>The best way to handle such a situation is to convert the component to separate library modules. This module can then be imported into both the projects. This also makes maintenance of this component easier and no copy paste needed, Yay!!. Here we are sharing the module (library) locally. But can’t this be done globally? Where one person writes components and makes it available for any developer to use it. If any developer using this component finds a bug, he can report it to the creator and wait for him to fix it or fix it himself. We all developers live in peace. 🙂</p>

<h3 id="how-to-build-a-library">How to build a library?</h3>

<ol>
  <li>
    <p>Let’s create a new empty project in Android and name it <em>“MyApp”</em>. On completing of creating a new project, the <em>“Project”</em> pane of Android Studio will look like this.
<img src="/assets/images/Screenshot-from-2019-07-14-16-18-18-2.png" alt="" class="align-center" />
Congratulations we have successfully created a new module. However, this is not the type of module we are here for. This is an application module, what we need is a library module. So let’s create one</p>
  </li>
  <li>
    <p>Go to <code class="language-plaintext highlighter-rouge">File -&gt; New -&gt; New module…</code> it will show us a popup asking for the type of module you want to add. Select <em>“Android Library”</em> from the list and click Next and then it will ask us to name our module. Let’s name it <em>“My Library”</em> and click Finish. After we complete this step our project pane will look like this. 
<img src="/assets/images/Screenshot-from-2019-07-14-16-53-20.png" alt="" class="align-center" />
Notice the <code class="language-plaintext highlighter-rouge">mylibrary</code> there? That’s the new library module which we just created. Android studio differentiate between them by showing a different icon for the app module and library module.</p>
  </li>
</ol>

<p>How does Android Studio know which one is an app module and which one is a library module? What changed? The answer is hidden inside the module level <code class="language-plaintext highlighter-rouge">build.gradle</code> file. If you open the app and library modules’ <code class="language-plaintext highlighter-rouge">build.gradle</code> you will see the first line of app’s Gradle file is</p>
<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">apply</span> <span class="nl">plugin:</span> <span class="s1">'com.android.application'</span>
</code></pre></div></div>
<p>and that of the library is</p>
<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">apply</span> <span class="nl">plugin:</span> <span class="s1">'com.android.library'</span>
</code></pre></div></div>

<p>This is what tells Android Studio what type of Module it is. Now we can write all of our fancy code inside the library module which we want to distribute.</p>

<p class="notice--success"><strong>Pro Tip:</strong> It’s considered good practice to make your library code configurable for most common use cases. Because, what we build our library for might not be the exact use case for the developer using the library.</p>

<h3 id="how-do-i-use-this-library-module-in-my-app">How do I use this library module in my app?</h3>
<p>Simple!! you just have to add one lie to your app module-level build.gradle file</p>
<div class="language-groovy highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">implementation</span> <span class="nf">project</span><span class="o">(</span><span class="nl">path:</span> <span class="s1">':mylibrary'</span><span class="o">)</span>
</code></pre></div></div>

<p>This will only work if your module is in the same project as your app.</p>

<p>If your library module is in some other project, you will have to import it to your current project or publish that library through JCenter. About which I will explain in my next post.</p>

<p>Since you have added this library as a dependency to the app module, now you can use the code/feature from the library as if it is a part of your project.</p>]]></content><author><name>Saran</name></author><category term="Android" /><category term="Android" /><category term="Android-Studio" /><category term="Bintray" /><category term="Jcenter" /><category term="Library" /><summary type="html"><![CDATA[When I started as an Android dev about 1.5 years back, I used to think, why do I need libraries when I can build all that cool stuff myself? However, as I completed about 2 months in the profession I started realizing the importance of the library and re-inventing the wheel every time was not at all a good idea. Every time I used a library from GitHub, I used to think, how do they build such cool library and how is it different from the normal app which I was used to building? If you wonder the same, you are in the right place. Today I will be explaining what libraries are, how you can build them, also why and how to distribute a library you built. What is a library? To know what is a library, you must know what a module is. Let’s learn what a module is. A Module in a project follows the Separation of Concern (S) from the SOLID principles of Object-Oriented Design.[*] Modules help in splitting a project into smaller modules which would run independently or dependently on other modules. Whenever we create a new project, Android Studio creates a single module which is an application module or app in short. App modules can run independently. Whereas, library modules cannot run independently. It is dependent on another application module which will invoke this library module for it to run. In Android, all of this is handled via build.gradle file of the application module. Why should I build them? When we work on multiple projects, we often write a lot of components in our project which we later need in other projects as well. What we end up doing is copy-pasting the code from project one to project two. Later we find that there was a bug in the component and we fix them in project two. However, the bug still exists in project one. Maintaining the same codebase twice is a challenging task and is not the best way to do it. The best way to handle such a situation is to convert the component to separate library modules. This module can then be imported into both the projects. This also makes maintenance of this component easier and no copy paste needed, Yay!!. Here we are sharing the module (library) locally. But can’t this be done globally? Where one person writes components and makes it available for any developer to use it. If any developer using this component finds a bug, he can report it to the creator and wait for him to fix it or fix it himself. We all developers live in peace. 🙂 How to build a library? Let’s create a new empty project in Android and name it “MyApp”. On completing of creating a new project, the “Project” pane of Android Studio will look like this. Congratulations we have successfully created a new module. However, this is not the type of module we are here for. This is an application module, what we need is a library module. So let’s create one Go to File -&gt; New -&gt; New module… it will show us a popup asking for the type of module you want to add. Select “Android Library” from the list and click Next and then it will ask us to name our module. Let’s name it “My Library” and click Finish. After we complete this step our project pane will look like this. Notice the mylibrary there? That’s the new library module which we just created. Android studio differentiate between them by showing a different icon for the app module and library module. How does Android Studio know which one is an app module and which one is a library module? What changed? The answer is hidden inside the module level build.gradle file. If you open the app and library modules’ build.gradle you will see the first line of app’s Gradle file is apply plugin: 'com.android.application' and that of the library is apply plugin: 'com.android.library' This is what tells Android Studio what type of Module it is. Now we can write all of our fancy code inside the library module which we want to distribute. Pro Tip: It’s considered good practice to make your library code configurable for most common use cases. Because, what we build our library for might not be the exact use case for the developer using the library. How do I use this library module in my app? Simple!! you just have to add one lie to your app module-level build.gradle file implementation project(path: ':mylibrary') This will only work if your module is in the same project as your app. If your library module is in some other project, you will have to import it to your current project or publish that library through JCenter. About which I will explain in my next post. Since you have added this library as a dependency to the app module, now you can use the code/feature from the library as if it is a part of your project.]]></summary></entry></feed>